Showing posts with label AWS News Blog. Show all posts

Monday, December 14, 2020

re:Invent 2020 Liveblog: Werner Vogels Keynote

Join us Tuesday, Dec. 15 for Dr. Werner Vogels’ Keynote as he shares how Amazon is solving today’s hardest technology problems. Jeff Barr, Martin Beeby, Steve Roberts and Channy Yun will liveblog the event, sharing all the highlights, insights and major announcements from this final keynote of re:Invent 2020.

See you here Tuesday, 7:30-10:00 AM (PST)!


Via AWS News Blog https://ift.tt/1EusYcK

Thursday, December 10, 2020

New – VPC Reachability Analyzer

With Amazon Virtual Private Cloud (VPC), you can launch a logically isolated customer-specific virtual network on the AWS Cloud. As customers expand their footprint on the cloud and deploy increasingly complex network architectures, it can take longer to resolve network connectivity issues caused by misconfiguration. Today, we are happy to announce VPC Reachability Analyzer, a network diagnostics tool that troubleshoots reachability between two endpoints in a VPC, or within multiple VPCs.

Ensuring Your Network Configuration is as Intended
You have full control over your virtual network environment, including choosing your own IP address range, creating subnets, and configuring route tables and network gateways. You can also easily customize the network configuration of your VPC. For example, you can create a public subnet for a web server that has access to the Internet with Internet Gateway. Security-sensitive backend systems such as databases and application servers can be placed on private subnets that do not have internet access. You can use multiple layers of security, such as security groups and network access control list (ACL), to control access to entities of each subnet by protocol, IP address, and port number.

You can also combine multiple VPCs via VPC peering or AWS Transit Gateway for region-wide, or global network connections that can route traffic privately. You can also use VPN Gateway to connect your site with your AWS account for secure communication. Many AWS services that reside outside the VPC, such as AWS Lambda, or Amazon S3, support VPC endpoints or AWS PrivateLink as entities inside the VPC and can communicate with those privately.

When you have such rich controls and feature set, it is not unusual to have unintended configuration that could lead to connectivity issues. Today, you can use VPC Reachability Analyzer for analyzing reachability between two endpoints without sending any packets. VPC Reachability analyzer looks at the configuration of all the resources in your VPCs and uses automated reasoning to determine what network flows are feasible. It analyzes all possible paths through your network without having to send any traffic on the wire. To learn more about how these algorithms work checkout this re:Invent talk or read this paper.

How VPC Reachability Analyzer Works
Let’s see how it works. Using VPC Reachability Analyzer is very easy, and you can test it with your current VPC. If you need an isolated VPC for test purposes, you can run the AWS CloudFormation YAML template at the bottom of this article. The template creates a VPC with 1 subnet, 2 security groups and 3 instances as A, B, and C. Instance A and B can communicate with each other, but those instances cannot communicate with instance C because the security group attached to instance C does not allow any incoming traffic.

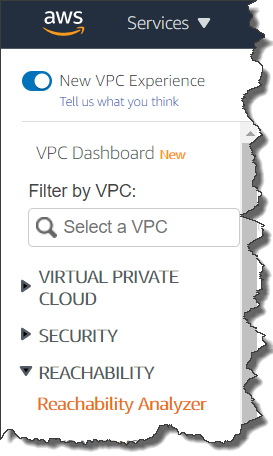
You see Reachability Analyzer in the left navigation of the VPC Management Console.

Click Reachability Analyzer, and also click Create and analyze path button, then you see new windows where you can specify a path between a source and destination, and start analysis.

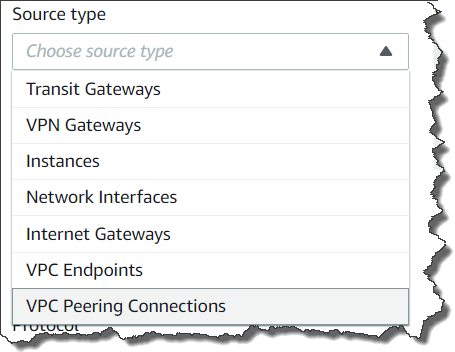
You can specify any of the following endpoint types: VPN Gateways, Instances, Network Interfaces, Internet Gateways, VPC Endpoints, VPC Peering Connections, and Transit Gateways for your source and destination of communication. For example, we set instance A for source and the instance B for destination. You can choose to check for connectivity via either the TCP or UDP protocols. Optionally, you can also specify a port number, or source, or destination IP address.

Configuring test path

Finally, click the Create and analyze path button to start the analysis. The analysis can take up to several minutes depending on the size and complexity of your VPCs, but it typically takes a few seconds.

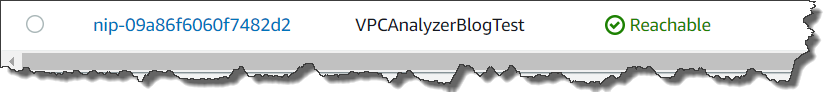
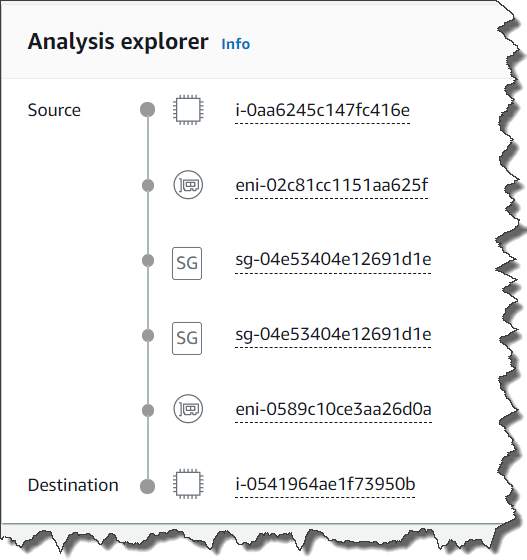
You can now see the analysis result as Reachable. If you click the URL link of analysis id nip-xxxxxxxxxxxxxxxxx, you can see the route hop by hop.

The communication from instance A to instance C is not reachable because the security group attached to instance C does not allow any incoming traffic.

If you click nip-xxxxxxxxxxxxxxxxx for more detail, you can check the Explanations for details.

Result Detail

Here we see the security group that blocked communication. When you click on the security group listed in the upper right corner, you can go directly to the security group editing window to change the security group rules. In this case adding a properly scoped ingress rule will allow the instances to communicate.

Available Today
This feature is available for all AWS commercial Regions except for China (Beijing), and China (Ningxia) regions.

– Kame

CloudFormation YAML template for test

---
Description: An AWS VPC configuration with 1 subnet, 2 security groups and 3 instances. When testing ReachabilityAnalyzer, this provides both a path found and path not found scenario.
AWSTemplateFormatVersion: 2010-09-09

Mappings:
  RegionMap:
    us-east-1:
      execution: ami-0915e09cc7ceee3ab
      ecs: ami-08087103f9850bddd

Resources:
  # VPC
  VPC:
    Type: AWS::EC2::VPC
    Properties:
      CidrBlock: 172.0.0.0/16
      EnableDnsSupport: true
      EnableDnsHostnames: true
      InstanceTenancy: default

  # Subnets
  Subnet1:
    Type: AWS::EC2::Subnet
    Properties:
      VpcId: !Ref VPC
      CidrBlock: 172.0.0.0/20
      MapPublicIpOnLaunch: false

  # SGs
  SecurityGroup1:
    Type: AWS::EC2::SecurityGroup
    Properties:
      GroupDescription: Allow all ingress and egress traffic
      VpcId: !Ref VPC
      SecurityGroupIngress:
        - CidrIp: 0.0.0.0/0
          IpProtocol: "-1" # -1 specifies all protocols

  SecurityGroup2:
    Type: AWS::EC2::SecurityGroup
    Properties:
      GroupDescription: Allow all egress traffic
      VpcId: !Ref VPC

  # Instances
  # Instance A and B should have a path between them since they are both in SecurityGroup 1
  InstanceA:
    Type: AWS::EC2::Instance
    Properties:
      ImageId:
        Fn::FindInMap:
          - RegionMap
          - Ref: AWS::Region
          - execution
      InstanceType: 't3.nano'
      SubnetId:
        Ref: Subnet1
      SecurityGroupIds:
        - Ref: SecurityGroup1

  # Instance A and B should have a path between them since they are both in SecurityGroup 1
  InstanceB:
    Type: AWS::EC2::Instance
    Properties:
      ImageId:
        Fn::FindInMap:
          - RegionMap
          - Ref: AWS::Region
          - execution
      InstanceType: 't3.nano'
      SubnetId:
        Ref: Subnet1
      SecurityGroupIds:
        - Ref: SecurityGroup1

  # This instance should not be reachable from Instance A or B since it is in SecurityGroup 2
  InstanceC:
    Type: AWS::EC2::Instance
    Properties:
      ImageId:
        Fn::FindInMap:
          - RegionMap
          - Ref: AWS::Region
          - execution
      InstanceType: 't3.nano'
      SubnetId:
        Ref: Subnet1
      SecurityGroupIds:
        - Ref: SecurityGroup2


Via AWS News Blog https://ift.tt/1EusYcK

Wednesday, December 9, 2020

re:Invent 2020 Liveblog: Infrastructure Keynote

Join us Thursday, Dec. 10 from 7:30-9:30 AM (PST) as we liveblog the AWS re:Invent Infrastructure Keynote with Peter DeSantis, senior vice president of AWS Global Infrastructure and Customer Support.

AWS Chief Evangelist Jeff Barr and Developer Advocates Martin Beeby and Steve Roberts will follow all the action with updates and insights as the event unfolds.

See you soon!


Via AWS News Blog https://ift.tt/1EusYcK

New – Amazon EMR on Amazon Elastic Kubernetes Service (EKS)

Tens of thousands of customers use Amazon EMR to run big data analytics applications on frameworks such as Apache Spark, Hive, HBase, Flink, Hudi, and Presto at scale. EMR automates the provisioning and scaling of these frameworks and optimizes performance with a wide range of EC2 instance types to meet price and performance requirements. Customer are now consolidating compute pools across organizations using Kubernetes. Some customers who manage Apache Spark on Amazon Elastic Kubernetes Service (EKS) themselves want to use EMR to eliminate the heavy lifting of installing and managing their frameworks and integrations with AWS services. In addition, they want to take advantage of the faster runtimes and development and debugging tools that EMR provides.

Today, we are announcing the general availability of Amazon EMR on Amazon EKS, a new deployment option in EMR that allows customers to automate the provisioning and management of open-source big data frameworks on EKS. With EMR on EKS, customers can now run Spark applications alongside other types of applications on the same EKS cluster to improve resource utilization and simplify infrastructure management.

Customers can deploy EMR applications on the same EKS cluster as other types of applications, which allows them to share resources and standardize on a single solution for operating and managing all their applications. Customers get all the same EMR capabilities on EKS that they use on EC2 today, such as access to the latest frameworks, performance optimized runtimes, EMR Notebooks for application development, and Spark user interface for debugging.

Amazon EMR automatically packages the application into a container with the big data framework and provides pre-built connectors for integrating with other AWS services. EMR then deploys the application on the EKS cluster and manages logging and monitoring. With EMR on EKS, you can get 3x faster performance using the performance-optimized Spark runtime included with EMR compared to standard Apache Spark on EKS.

Amazon EMR on EKS – Getting Started
If you already have a EKS cluster where you run Spark jobs, you simply register your existing EKS cluster with EMR using the AWS Management Console, AWS Command Line Interface (CLI) or APIs to deploy your Spark appication.

For exampe, here is a simple CLI command to register your EKS cluster.

$ aws emr create-virtual-cluster \
          --name <virtual_cluster_name> \
          --container-provider '{
             "id": "<eks_cluster_name>",
             "type": "EKS",
             "info": {
                 "eksInfo": {
                     "namespace": "<namespace_name>"
                 }
             } 
         }'

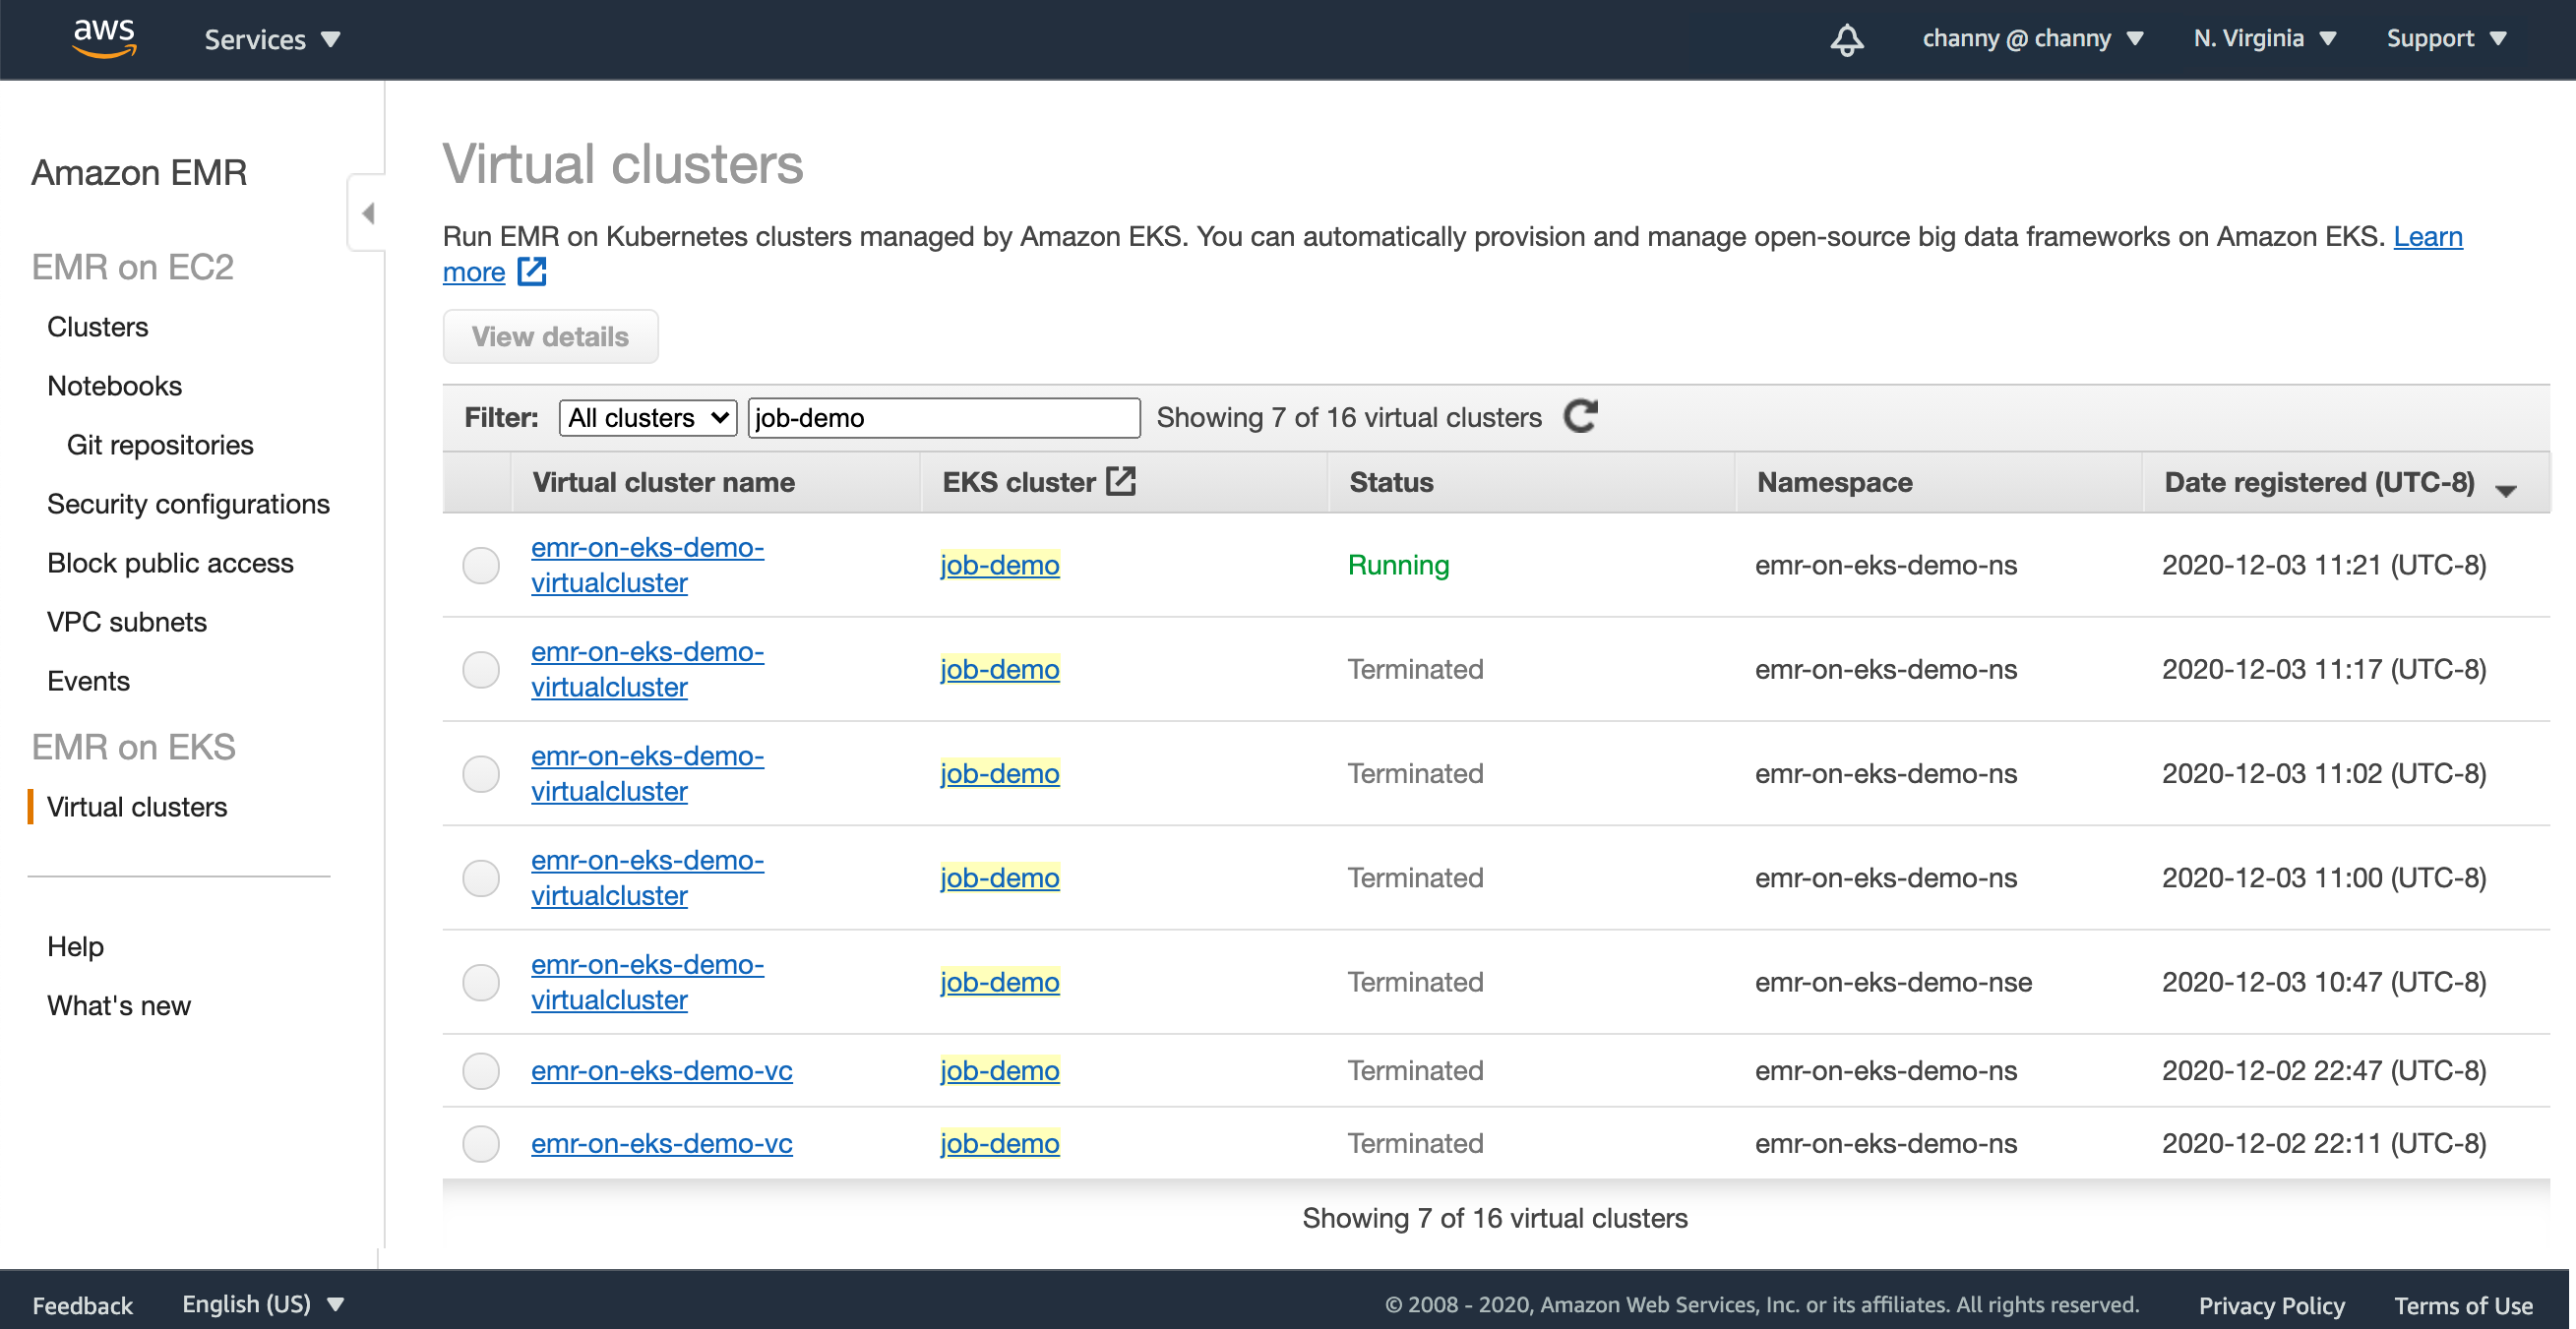
In the EMR Management console, you can see it in the list of virtual clusters.

When Amazon EKS clusters are registered, EMR workloads are deployed to Kubernates nodes and pods to manage application execution and auto-scaling, and sets up managed endpoints so that you can connect notebooks and SQL clients. EMR builds and deploys a performance-optimized runtime for the open source frameworks used in analytics applications.

You can simply start your Spark jobs.

$ aws emr start-job-run \
          --name <job_name> \
          --virtual-cluster-id <cluster_id> \
          --execution-role-arn <IAM_role_arn> \
          --virtual-cluster-id <cluster_id> \
          --release-label <<emr_release_label> \
          --job-driver '{
            "sparkSubmitJobDriver": {
              "entryPoint": <entry_point_location>,
              "entryPointArguments": ["<arguments_list>"],
              "sparkSubmitParameters": <spark_parameters>
            }
       }'

To monitor and debug jobs, you can use inspect logs uploaded to your Amazon CloudWatch and Amazon Simple Storage Service (S3) location configured as part of monitoringConfiguration. You can also use the one-click experience from the console to launch the Spark History Server.

Integration with Amazon EMR Studio

Now you can submit analytics applications using AWS SDKs and AWS CLI, Amazon EMR Studio notebooks, and workflow orchestration services like Apache Airflow. We have developed a new Airflow Operator for Amazon EMR on EKS. You can use this connector with self-managed Airflow or by adding it to the Plugin Location with Amazon Managed Workflows for Apache Airflow.

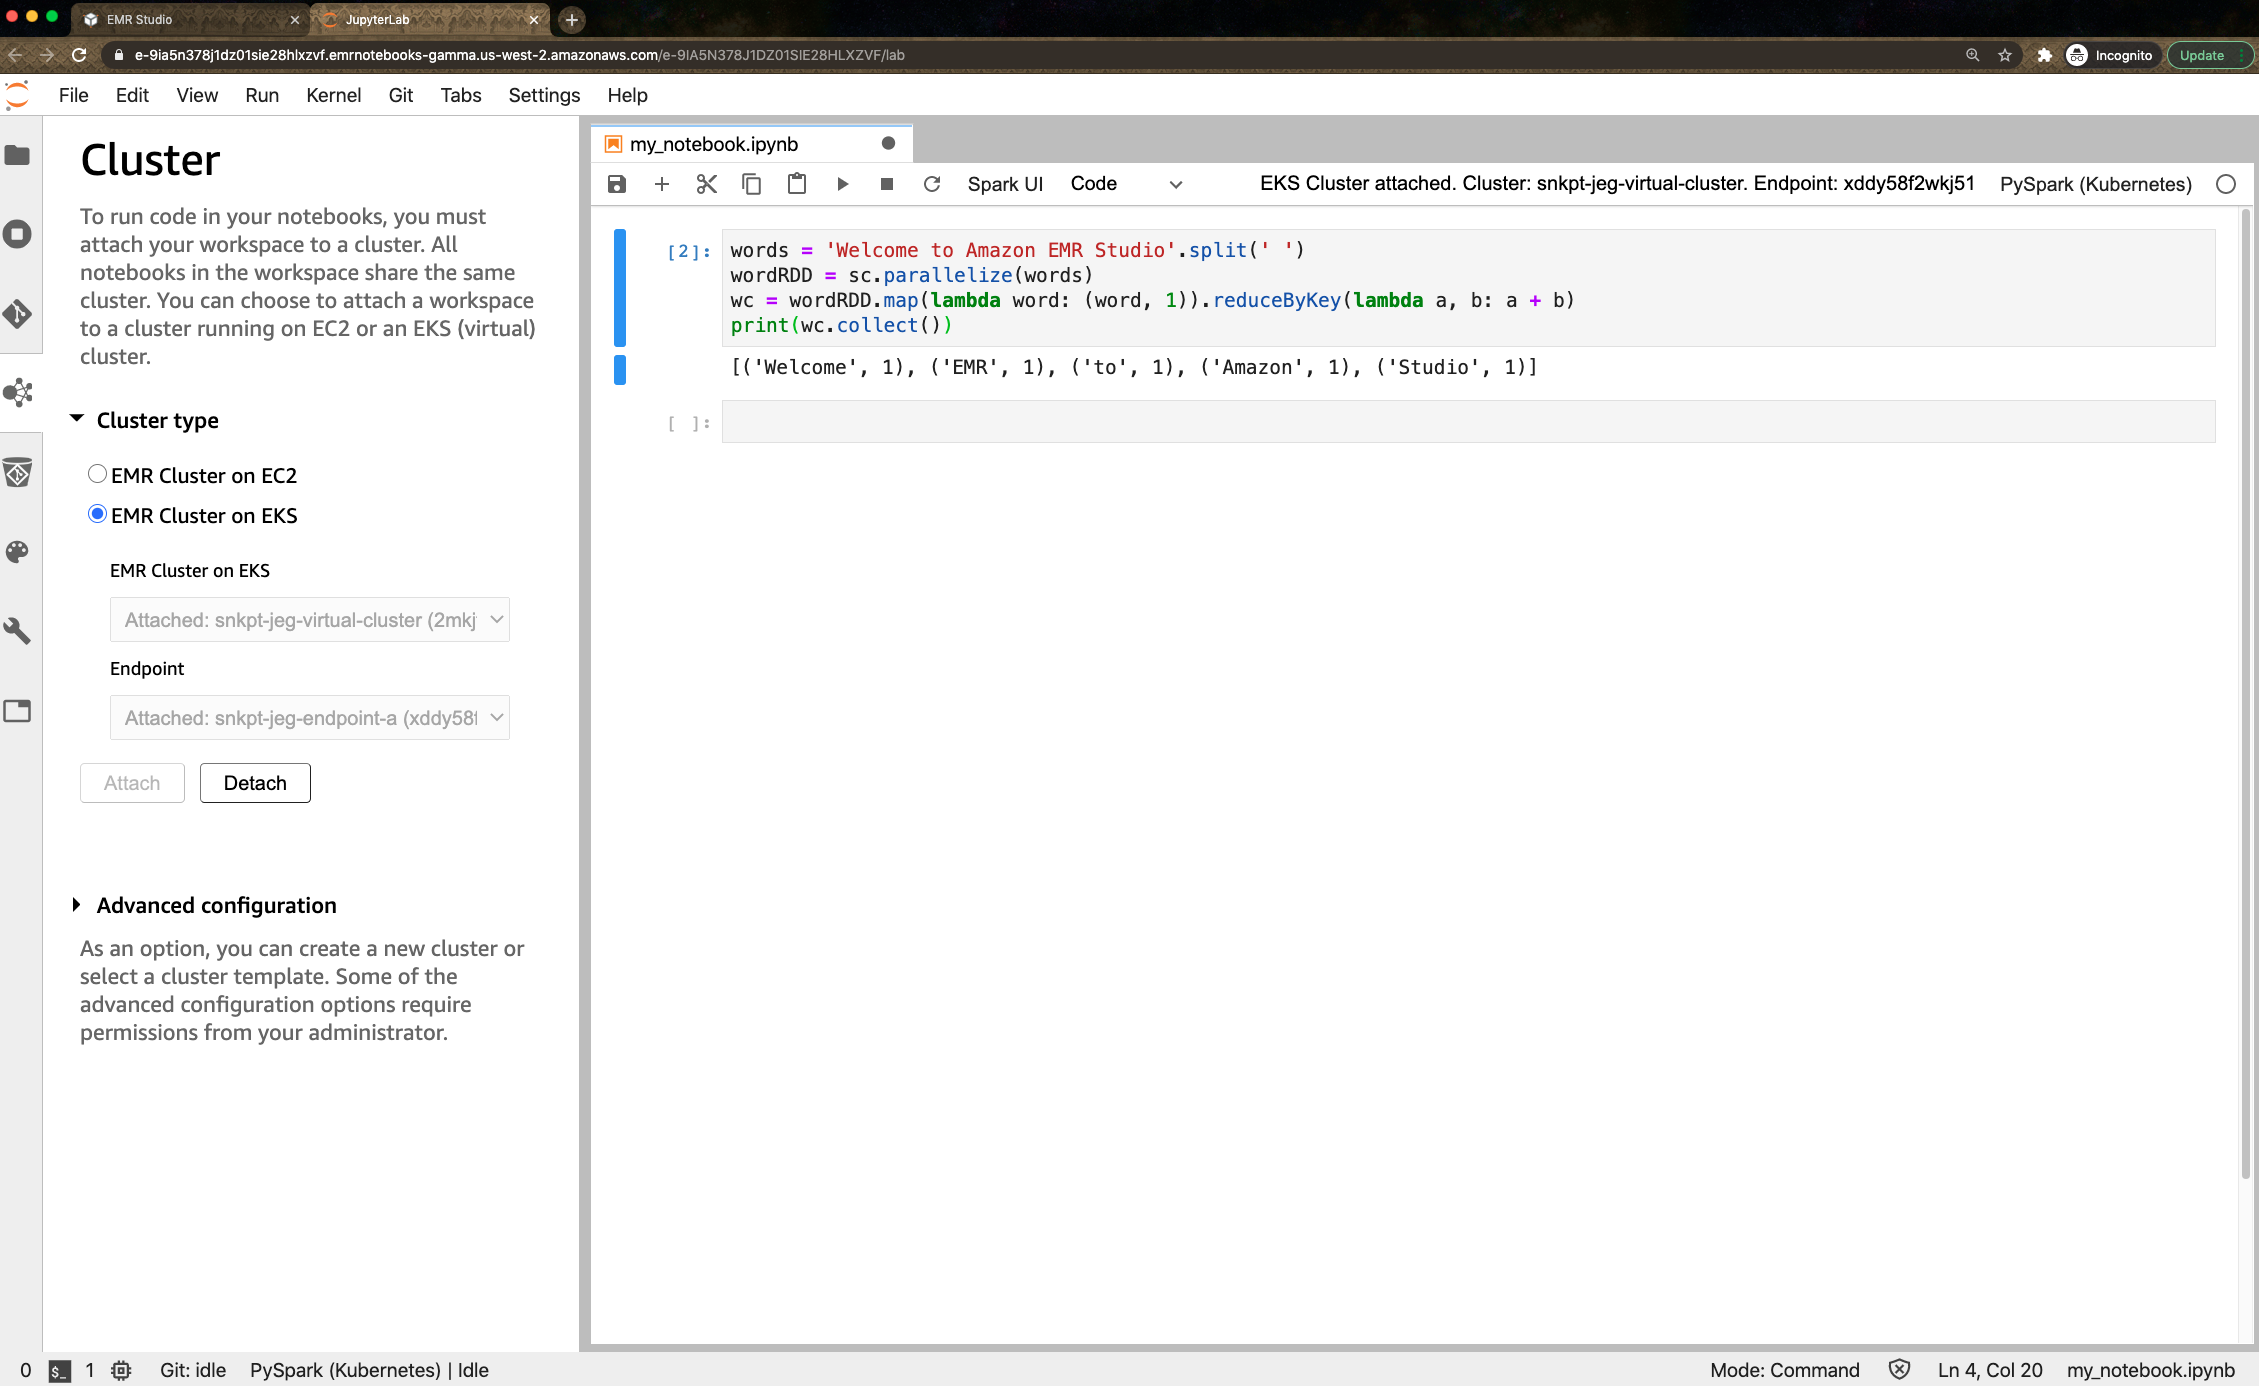
You can also use newly previewed Amazon EMR Studio to perform data analysis and data engineering tasks in a web-based integrated development environment (IDE). Amazon EMR Studio lets you submit notebook code to EMR clusters deployed on EKS using the Studio interface. After seting up one or more managed endpoints to which Studio users can attach a Workspace, EMR Studio can communicate with your virtual cluster.

For EMR Studio preview, there is no additional cost when you create managed endpoints for virtual clusters. To learn more, visit the guide document.

Now Available
Amazon EMR on Amazon EKS is available in US East (N. Virginia), US West (Oregon), and Europe (Ireland) Regions. You can run EMR workloads in AWS Fargate for EKS removing the need to provision and manage infrastructure for pods as a serverless option.

To learn more, visit the documentation. Please send feedback to the AWS forum for Amazon EMR or through your usual AWS support contacts.

Learn all the details about Amazon EMR on Amazon EKS and get started today.

Channy;

Via AWS News Blog https://ift.tt/1EusYcK

Tuesday, December 8, 2020

PennyLane on Braket + Progress Toward Fault-Tolerant Quantum Computing + Tensor Network Simulator

I first wrote about Amazon Braket last year and invited you to Get Started with Quantum Computing! Since that launch we have continued to push forward, and have added several important & powerful new features to Amazon Braket:

August 2020 – General Availability of Amazon Braket with access to quantum computing hardware from D-Wave, IonQ, and Rigetti.

September 2020 – Access to D-Wave’s Advantage Quantum Processing Unit (QPU), which includes more than 5,000 qubits and 15-way connectivity.

November 2020 – Support for resource tagging, AWS PrivateLink, and manual qubit allocation. The first two features make it easy for you to connect your existing AWS applications to the new ones that you build with Amazon Braket, and should help you to envision what a production-class cloud-based quantum computing application will look like in the future. The last feature is particularly interesting to researchers; from what I understand, certain qubits within a given piece of quantum computing hardware can have individual physical and connectivity properties that might make them perform somewhat better when used as part of a quantum circuit. You can read about Allocating Qubits on QPU Devices to learn more (this is somewhat similar to the way that a compiler allocates CPU registers to frequently used variables).

In my initial blog post I also announced the formation of the AWS Center for Quantum Computing adjacent to Caltech.

As I write this, we are in the Noisy Intermediate Scale Quantum (NISQ) era. This description captures the state of the art in quantum computers: each gate in a quantum computing circuit introduces a certain amount of accuracy-destroying noise, and the cumulative effect of this noise imposes some practical limits on the scale of the problems.

Update Time
We are working to address this challenge, as are many others in the quantum computing field. Today I would like to give you an update on what we are doing at the practical and the theoretical level.

Similar to the way that CPUs and GPUs work hand-in-hand to address large scale classical computing problems, the emerging field of hybrid quantum algorithms joins CPUs and QPUs to speed up specific calculations within a classical algorithm. This allows for shorter quantum executions that are less susceptible to the cumulative effects of noise and that run well on today’s devices.

Variational quantum algorithms are an important type of hybrid quantum algorithm. The classical code (in the CPU) iteratively adjusts the parameters of a parameterized quantum circuit, in a manner reminiscent of the way that a neural network is built by repeatedly processing batches of training data and adjusting the parameters based on the results of an objective function. The output of the objective function provides the classical code with guidance that helps to steer the process of tuning the parameters in the desired direction. Mathematically (I’m way past the edge of my comfort zone here), this is called differentiable quantum computing.

So, with this rather lengthy introduction, what are we doing?

First, we are making the PennyLane library available so that you can build hybrid quantum-classical algorithms and run them on Amazon Braket. This library lets you “follow the gradient” and write code to address problems in computational chemistry (by way of the included Q-Chem library), machine learning, and optimization. My AWS colleagues have been working with the PennyLane team to create an integrated experience when PennyLane is used together with Amazon Braket.

PennyLane is pre-installed in Braket notebooks and you can also install the Braket-PennyLane plugin in your IDE. Once you do this, you can train quantum circuits as you would train neural networks, while also making use of familiar machine learning libraries such as PyTorch and TensorFlow. When you use PennyLane on the managed simulators that are included in Amazon Braket, you can train your circuits up to 10 times faster by using parallel circuit execution.

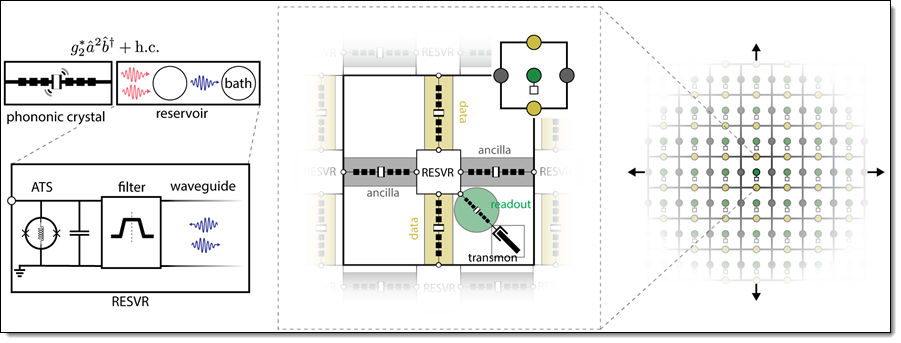
Second, the AWS Center for Quantum Computing is working to address the noise issue in two different ways: we are investigating ways to make the gates themselves more accurate, while also working on the development of more efficient ways to encode information redundantly across multiple qubits. Our new paper, Building a Fault-Tolerant Quantum Computer Using Concatenated Cat Codes speaks to both of these efforts. While not light reading, the 100+ page paper proposes the construction of a 2-D grid of micron-scale electro-acoustic qubits that are coupled via superconducting circuits:

Interestingly, this proposed qubit design was used to model a Toffoli gate, and then tested via simulations that ran for 170 hours on c5.18xlarge instances. In a very real sense, the classical computers are being used to design and then simulate their future quantum companions.

The proposed hybrid electro-acoustic qubits are far smaller than what is available today, and also offer a > 10x reduction in overhead (measured in the number of physical qubits required per error-corrected qubit and the associated control lines). In addition to working on the experimental development of this architecture based around hybrid electro-acoustic qubits, the AWS CQC team will also continue to explore other promising alternatives for fault-tolerant quantum computing to bring new, more powerful computing resources to the world.

And Third, we are expanding the choice of managed simulators that are available on Amazon Braket. In addition to the state vector simulator (which can simulate up to 34 qubits), you can use the new tensor network simulator that can simulate up to 50 qubits for certain circuits. This simulator builds a graph representation of the quantum circuit and uses the graph to find an optimized way to process it.

Help Wanted
If you are ready to help us to push the state of the art in quantum computing, take a look at our open positions. We are looking for Quantum Research Scientists, Software Developers, Hardware Developers, and Solutions Architects.

Time to Learn
It is still Day One (as we often say at Amazon) when it comes to quantum computing and now is the time to learn more and to get some experience with. Be sure to check out the Braket Tutorials repository and let me know what you think.

Jeff;

PS – If you are ready to start exploring ways that you can put quantum computing to work in your organization, be sure to take a look at the Amazon Quantum Solutions Lab.

Via AWS News Blog https://ift.tt/1EusYcK

New for Amazon CodeGuru – Python Support, Security Detectors, and Memory Profiling

Amazon CodeGuru is a developer tool that helps you improve your code quality and has two main components:

  • CodeGuru Reviewer uses program analysis and machine learning to detect potential defects that are difficult to find in your code and offers suggestions for improvement.
  • CodeGuru Profiler collects runtime performance data from your live applications, and provides visualizations and recommendations to help you fine-tune your application performance.

Today, I am happy to announce three new features:

  • Python Support for CodeGuru Reviewer and Profiler (Preview) – You can now use CodeGuru to improve applications written in Python. Before this release, CodeGuru Reviewer could analyze Java code, and CodeGuru Profiler supported applications running on a Java virtual machine (JVM).
  • Security Detectors for CodeGuru Reviewer – A new set of detectors for CodeGuru Reviewer to identify security vulnerabilities and check for security best practices in your Java code.
  • Memory Profiling for CodeGuru Profiler – A new visualization of memory retention per object type over time. This makes it easier to find memory leaks and optimize how your application is using memory.

Let’s see these functionalities in more detail.

Python Support for CodeGuru Reviewer and Profiler (Preview)
Python Support for CodeGuru Reviewer is available in Preview and offers recommendations on how to improve the Python code of your applications in multiple categories such as concurrency, data structures and control flow, scientific/math operations, error handling, using the standard library, and of course AWS best practices.

You can now also use CodeGuru Profiler to collect runtime performance data from your Python applications and get visualizations to help you identify how code is running on the CPU and where time is consumed. In this way, you can detect the most expensive lines of code of your application. Focusing your tuning activities on those parts helps you reduce infrastructure cost and improve application performance.

Let’s see the CodeGuru Reviewer in action with some Python code. When I joined AWS eight years ago, one of the first projects I created was a Filesystem in Userspace (FUSE) interface to Amazon Simple Storage Service (S3) called yas3fs (Yet Another S3-backed File System). It was inspired by the more popular s3fs-fuse project but rewritten from scratch to implement a distributed cache synchronized by Amazon Simple Notification Service (SNS) notifications (now, thanks to the many contributors, it’s using S3 event notifications). It was also a good excuse for me to learn more about Python programming and S3. It’s a personal project that at the time was made available as open source. Today, if you need a shared file system, you can use Amazon Elastic File System (EFS).

In the CodeGuru console, I associate the yas3fs repository. You can associate repositories from GitHub, including GitHub Enterprise Cloud and GitHub Enterprise Server, Bitbucket, or AWS CodeCommit.

After that, I can get a code review from CodeGuru in two ways:

  • Automatically, when I create a pull request. This is a great way to use it as you and your team are working on a code base.
  • Manually, creating a repository analysis to get a code review for all the code in one branch. This is useful to start using GodeGuru with an existing code base.

Since I just associated the whole repository, I go for a full analysis and write down the branch name to review (apologies, I was still using master at the time, now I use main for new projects).

After a few minutes, the code review is completed, and there are 14 recommendations. Not bad, but I can definitely improve the code. Here’s a few of the recommendations I get. I was using exceptions and global variables too much at the time.

Security Detectors for CodeGuru Reviewer
The new CodeGuru Reviewer Security Detector uses automated reasoning to analyze all code paths and find potential security issues deep in your Java code, even ones that span multiple methods and files and that may involve multiple sequences of operations. To build this detector, we used learning and best practices from Amazon’s 20+ years of experience.

The Security Detector is also identifying security vulnerabilities in the top 10 Open Web Application Security Project (OWASP) categories, such as weak hash encryption.

If the security detector discovers an issue, it offers a suggested remediation along with an explanation. In this way, it’s much easier to follow security best practices for AWS APIs, such as those for AWS Key Management Service (KMS) and Amazon Elastic Compute Cloud (EC2), and for common Java cryptography and TLS/SSL libraries.

With help from the security detector, security engineers can focus on architectural and application-specific security best-practices, and code reviewers can focus their attention on other improvements.

Memory Profiling for CodeGuru Profiler
For applications running on a JVM, CodeGuru Profiler can now show the Heap Summary, a consolidated view of memory retention during a time frame, tracking both overall sizes and number of objects per object type (such as String, int, char[], and custom types). These metrics are presented in a timeline graph, so that you can easily spot trends and peaks of memory utilization per object type.

Here are a couple of scenarios where this can help:

Memory Leaks – A constantly growing memory utilization curve for one or more object types may indicate a leak (intended here as unnecessary retention of memory objects by the application), possibly leading to out-of-memory errors and application crashes.

Memory Optimizations – Having a breakdown of memory utilization per object type is a step beyond traditional memory utilization monitoring, based solely on JVM-level metrics like total heap usage. By knowing that an unexpectedly high amount of memory has been associated with a specific object type, you can focus your analysis and optimization efforts on the parts of your application that are responsible for allocating and referencing objects of that type.

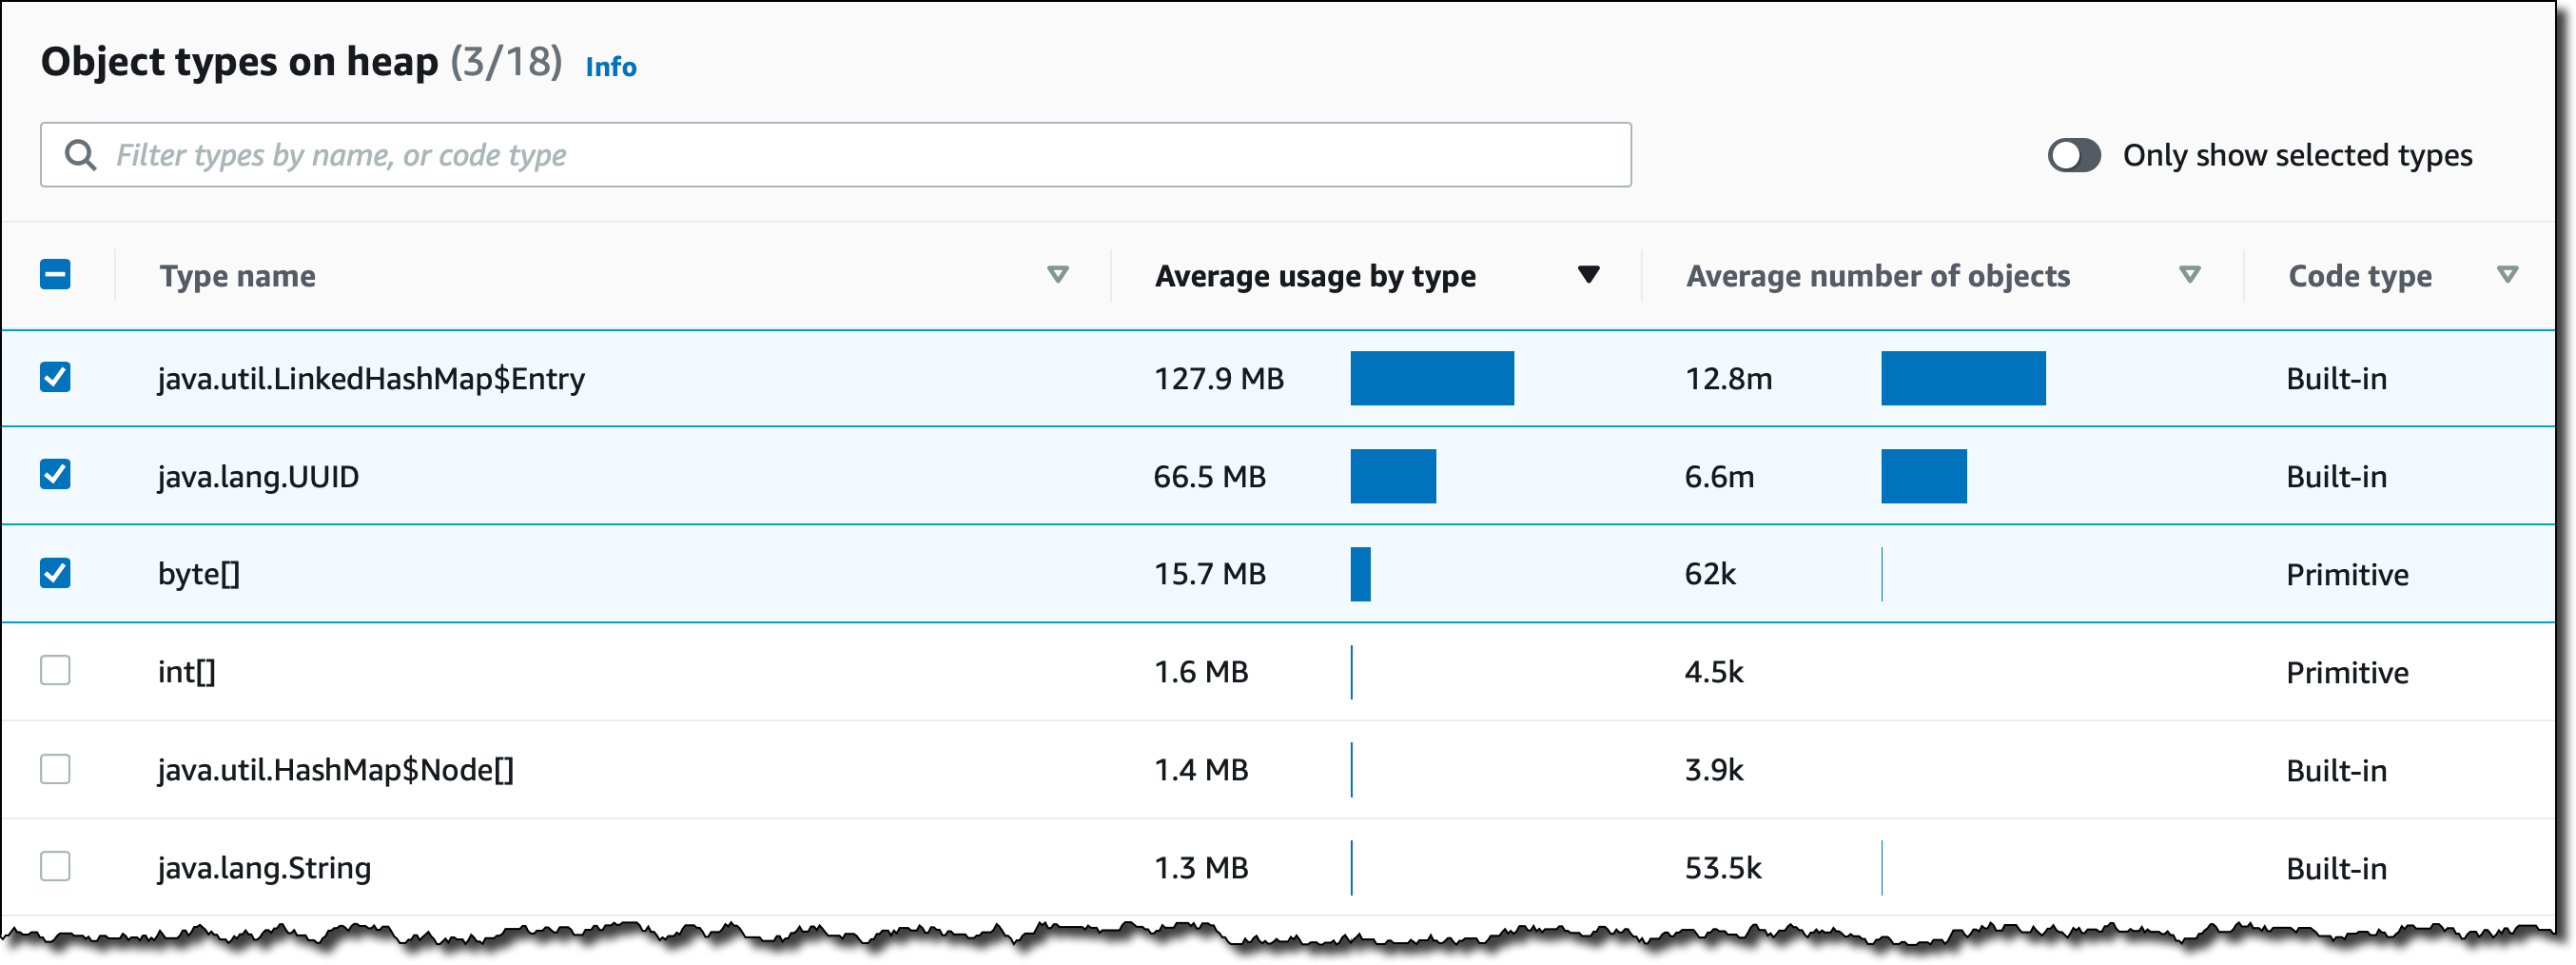
For example, here is a graph showing how memory is used by a Java application over an interval of time. Apart from the total capacity available and the used space, I can see how memory is being used by some specific object types, such as byte[], java.lang.UUID, and the entries of a java.util.LinkedHashMap. The continuous growth over time of the memory retained by these object types is suspicious. There is probably a memory leak I have to investigate.

In the table just below, I have a longer list of object types allocating memory on the heap. The first three are selected and for that reason are shown in the graph above. Here, I can inspect other object types and select them to see their memory usage over time. It looks like the three I already selected are the ones with more risk of being affected by a memory leak.

Available Now
These new features are available today in all regions where Amazon CodeGuru is offered. For more information, please see the AWS Regional Services table.

There are no pricing changes for Python support, security detectors, and memory profiling. You pay for what you use without upfront fees or commitments.

Learn more about Amazon CodeGuru and start using these new features today to improve the code quality of your applications.  

Danilo

Via AWS News Blog https://ift.tt/1EusYcK

AWS Audit Manager Simplifies Audit Preparation

Gathering evidence in a timely manner to support an audit can be a significant challenge due to manual, error-prone, and sometimes, distributed processes. If your business is subject to compliance requirements, preparing for an audit can cause significant lost productivity and disruption as a result. You might also have trouble applying traditional audit practices, which were originally designed for legacy on-premises systems, to your cloud infrastructure.

To satisfy complex and evolving sets of regulation and compliance standards, including the General Data Protection Regulation (GDPR), Health Insurance Portability and Accountability Act (HIPAA), and Payment Card Industry Data Security Standard (PCI DSS), you’ll need to gather, verify, and synthesize evidence.

You’ll also need to constantly reevaluate how your AWS usage maps to those evolving compliance control requirements. To satisfy requirements you may need to show data encryption was active, and log files showing server configuration changes, diagrams showing application high availability, transcripts showing required training was completed, spreadsheets showing that software usage did not exceed licensed amounts, and more. This effort, sometimes involving dozens of staff and consultants, can last several weeks.

Available today, AWS Audit Manager is a fully managed service that provides prebuilt frameworks for common industry standards and regulations, and automates the continual collection of evidence to help you in preparing for an audit. Continuous and automated gathering of evidence related to your AWS resource usage helps simplify risk assessment and compliance with regulations and industry standards and helps you maintain a continuous, audit-ready posture to provide a faster, less disruptive preparation process.

Built-in and customizable frameworks map usage of your cloud resources to controls for different compliance standards, translating evidence into an audit-ready, immutable assessment report using auditor-friendly terminology. You can also search, filter, and upload additional evidence to include in the final assessment, such as details of on-premises infrastructure, or procedures such as business continuity plans, training transcripts, and policy documents.

Given that audit preparation typically involves multiple teams, a delegation workflow feature lets you assign controls to subject-matter experts for review. For example, you might delegate reviewing evidence of network security to a network security engineer.

The finalized assessment report includes summary statistics and a folder containing all the evidence files, organized in accordance with the exact structure of the associated compliance framework. With the evidence collected and organized into a single location, it’s ready for immediate review, making it easier for audit teams to verify the evidence, answer questions, and add remediation plans.

Getting started with Audit Manager
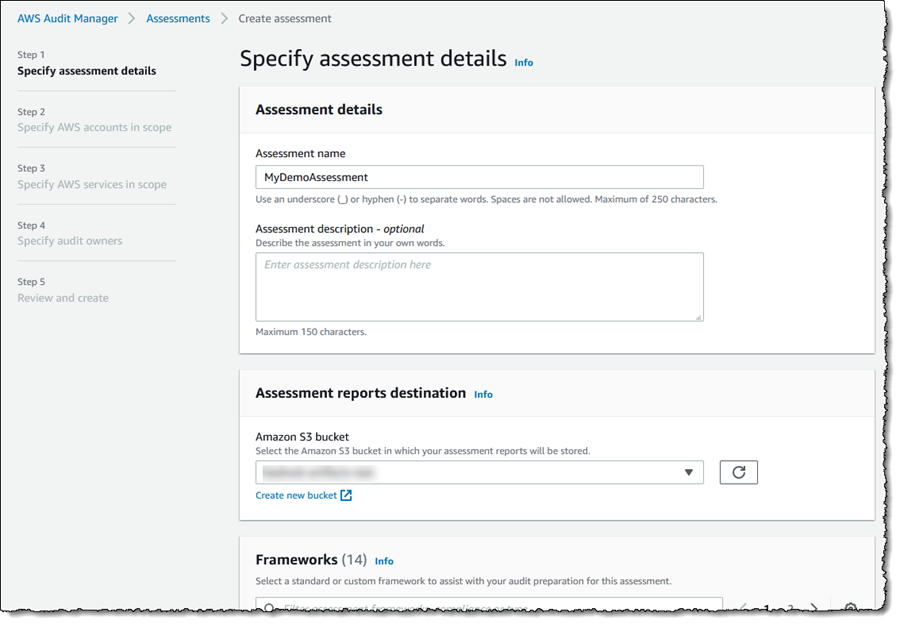
Let’s get started by creating and configuring a new assessment. From Audit Manager‘s console home page, clicking Launch AWS Audit Manager takes me to my Assessments list (I can also reach here from the navigation toolbar to the left of the console home). There, I click Create assessment to start a wizard that walks me through the settings for the new assessment. First, I give my assessment a name, optional description, and then specify an Amazon Simple Storage Service (S3) bucket where the reports associated with the assessment will be stored.

Next, I choose the framework for my assessment. I can select from a variety of prebuilt frameworks, or a custom framework I have created myself. Custom frameworks can be created from scratch or based on an existing framework. Here, I’m going to use the prebuilt PCI DSS framework.

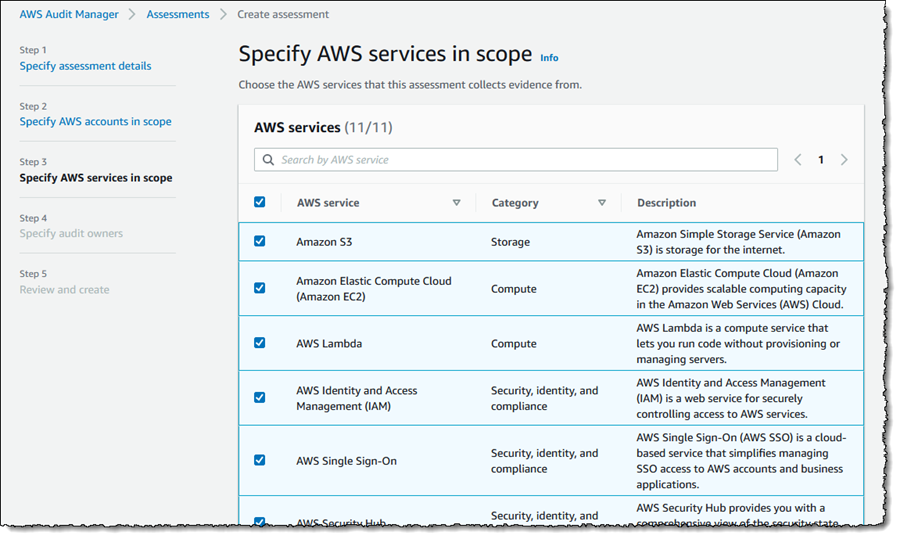
Screenshot of framework selectionAfter clicking Next, I can select the AWS accounts to be included in my assessment (Audit Manager is also integrated with AWS Organizations). Since I have a single account, I select it and click Next, moving on to select the AWS services that I want to be included in evidence gathering. I’m going to include all the suggested services (the default) and click Next to continue.

Screenshot of service selection for assessmentNext I need to select the owners of the assessment, who have full permission to manage it (owners can be AWS Identity and Access Management (IAM) users or roles). You must select at least one owner, so I select my account and click Next to move to the final Review and create page. Finally, clicking Create assessment starts the gathering of evidence for my new assessment. This can take a while to complete, so I’m going to switch to another assessment to examine what kinds of evidence I can view and choose to include in my assessment report.

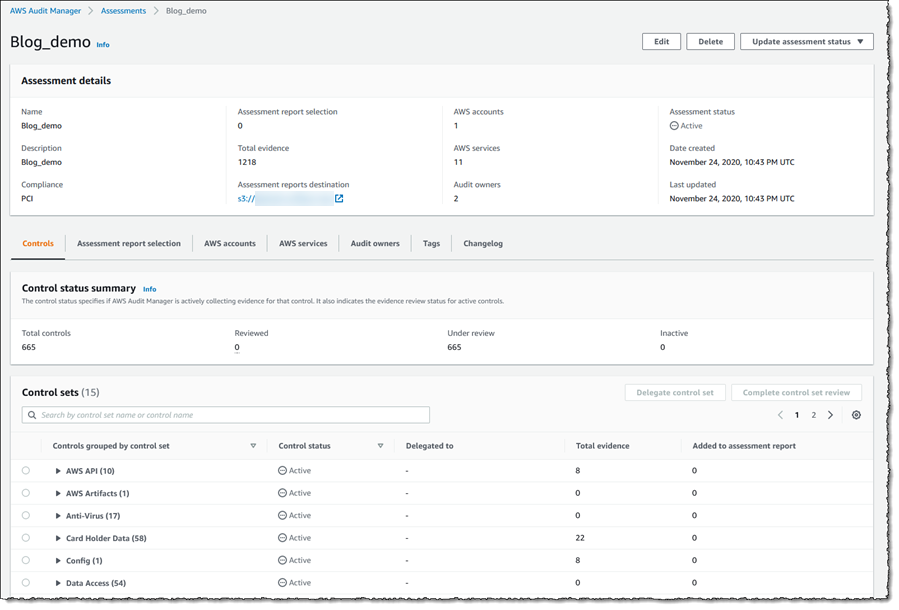
Back in the Assessments list view, clicking on the assessment name takes me to details of the assessment, a summary of the controls for which evidence is being collected, and a list of the control sets into which the controls are grouped. Total evidence tells me the number of events and supporting documents that are included in the assessment. The additional tabs can be used to give me insight into the evidence I select for the final report, which accounts and services are included in the assessment, who owns it, and more. I can also navigate to the S3 bucket in which the evidence is being collected.

Screenshot of assessment home pageExpanding a control set shows me the related controls, with links to dive deeper on a given control, together with the status (Under review, Reviewed, and Inactive), whom the control has been delegated to for review, the amount of evidence gathered for that control, and whether the control and evidence have been added to the final report. If I change a control to be Inactive, meaning automated evidence gathering will cease for that control, this is logged.

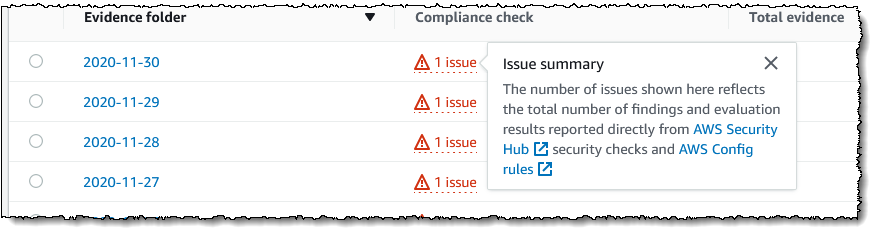
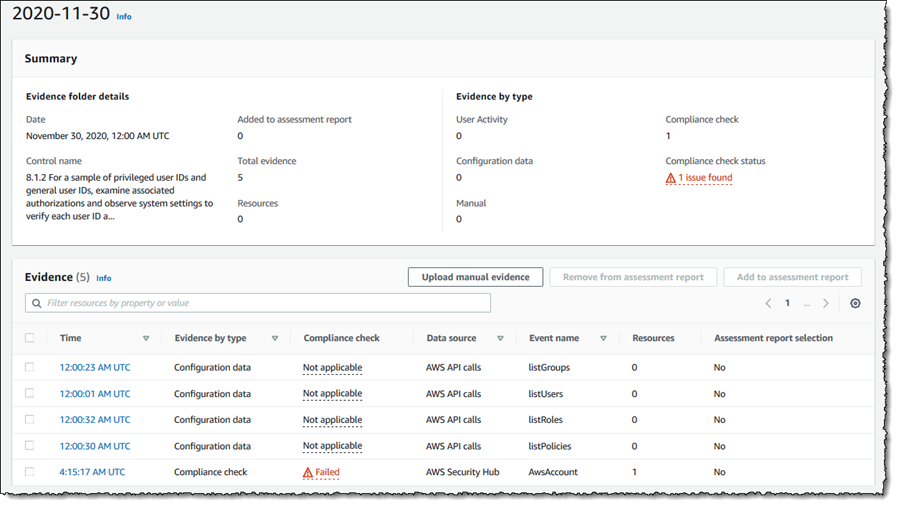
Screenshot of assessment controlLet’s take a closer look at a control to show how the automated evidence gathering can help identify compliance issues before I start compiling the audit report. Expanding Default control set, I click control 8.1.2 For a sample of privileged user IDs… which takes me to a view giving more detailed information on the control and how it is tested. Scrolling down, there is a set of evidence folders listed and here I notice that there are some issues. Clicking the issue link in the Compliance check column summarizes where the data came from. Here, I can also select the evidence that I want included in my final report.

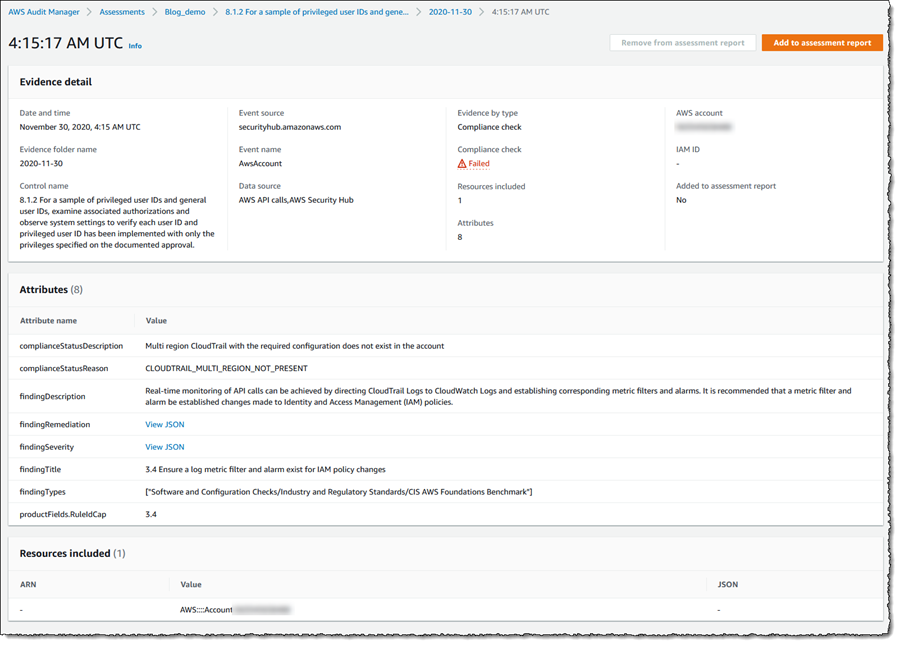
Screenshot of issue summaryGoing further, I can click on the evidence folder to note that there was a failure, and in turn clicking on the time of the failure takes me to a detailed summary of the issues for this control, and how to remediate.

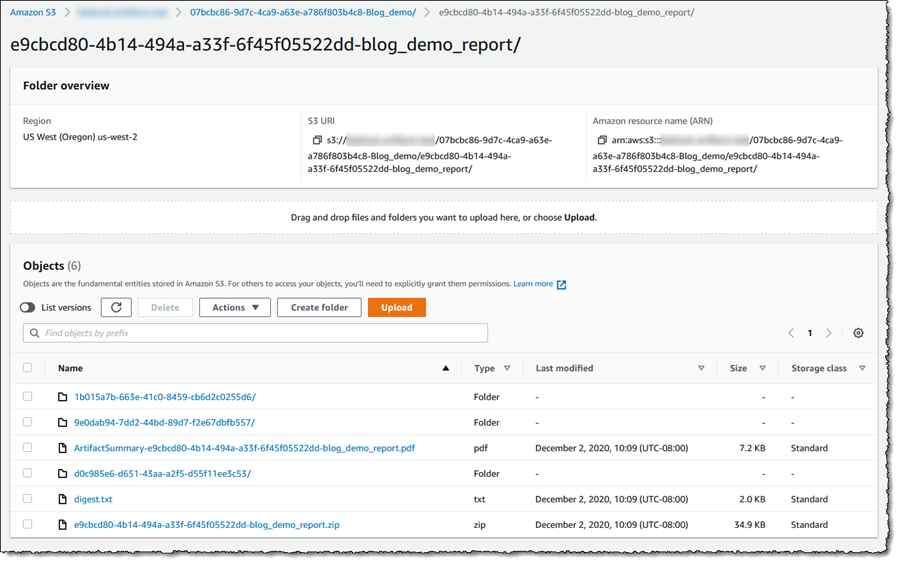
Screenshot of evidence for a controlScreenshot of evidence detailWith the evidence gathered, it’s a simple task to select sufficient controls and appropriate evidence to include in my assessment report that can then be passed to my auditors. For the purposes of this post I’ve gone ahead and selected evidence for a handful of controls into my report. Then, I selected the Assessment report selection tab, where I review my evidence selections, and clicked Generate assessment report. In the dialog that appeared I gave my report a name, and then clicked Generate assessment report. When the dialog closes I am taken to the Assessment reports view and, when my report is ready, I can select it and download a zip file containing the report and the selected evidence. Alternatively, I can open the S3 bucket associated with the assessment (from the assessment’s details page) and view the report details and evidence there, as shown in the screenshot below. The overall report is listed (as a PDF file) and if I drill into the evidence folders, I can also view PDF files related to the specific items of evidence I selected.

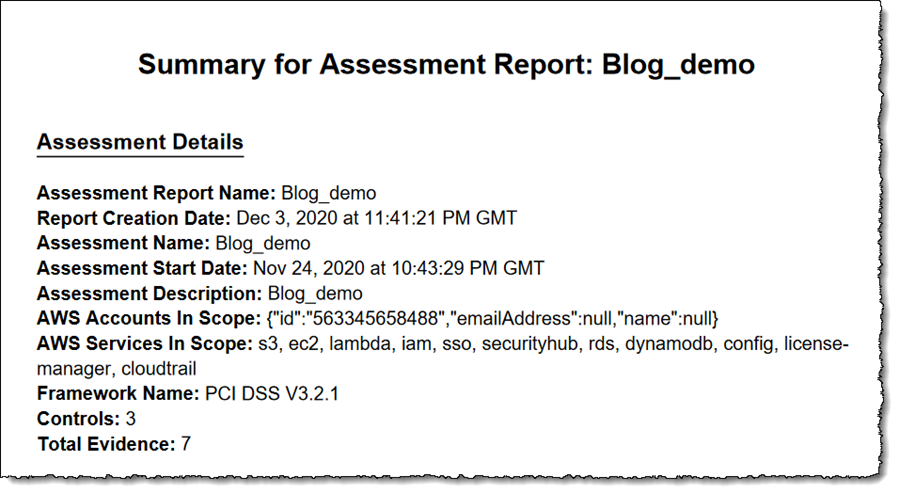
Screenshot of assessment report output in S3And to close, below is a screenshot of the beginning of the assessment report PDF file showing the number of selected controls and evidence, and services that I selected to be in scope when I created the assessment. Further pages go into more details.

Screenshot of assessment reportAudit Manager is available today in 10 AWS Regions: US East (Northern Virginia, Ohio), US West (Northern California, Oregon), Asia Pacific (Singapore, Sydney, Tokyo), and Europe (Frankfurt, Ireland, London).

Get all the details about AWS Audit Manager and get started today.

— Steve Via AWS News Blog https://ift.tt/1EusYcK

Amazon SageMaker JumpStart Simplifies Access to Pre-built Models and Machine Learning Solutions

Today, I’m extremely happy to announce the availability of Amazon SageMaker JumpStart, a capability of Amazon SageMaker that accelerates your machine learning workflows with one-click access to popular model collections (also known as “model zoos”), and to end-to-end solutions that solve common use cases.

In recent years, machine learning (ML) has proven to be a valuable technique in improving and automating business processes. Indeed, models trained on historical data can accurately predict outcomes across a wide range of industry segments: financial services, retail, manufacturing, telecom, life sciences, and so on. Yet, working with these models requires skills and experience that only a subset of scientists and developers have: preparing a dataset, selecting an algorithm, training a model, optimizing its accuracy, deploying it in production, and monitoring its performance over time.

In order to simplify the model building process, the ML community has created model zoos, that is to say, collections of models built with popular open source libraries, and often pretrained on reference datasets. For example, the TensorFlow Hub and the PyTorch Hub provide developers with a long list of models ready to be downloaded, and integrated in applications for computer vision, natural language processing, and more.

Still, downloading a model is just part of the answer. Developers then need to deploy it for evaluation and testing, using either a variety of tools, such as the TensorFlow Serving and TorchServe model servers, or their own bespoke code. Once the model is running, developers need to figure out the correct format that incoming data should have, a long-lasting pain point. I’m sure I’m not the only one regularly pulling my hair out here!

Of course, a full-ML application usually has a lot of moving parts. Data needs to be preprocessed, enriched with additional data fetched from a backend, and funneled into the model. Predictions are often postprocessed, and stored for further analysis and visualization. As useful as they are, model zoos only help with the modeling part. Developers still have lots of extra work to deliver a complete ML solution.

Because of all this, ML experts are flooded with a long backlog of projects waiting to start. Meanwhile, less experienced practitioners struggle to get started. These barriers are incredibly frustrating, and our customers asked us to remove them.

Introducing Amazon SageMaker JumpStart
Amazon SageMaker JumpStart is integrated in Amazon SageMaker Studio, our fully integrated development environment (IDE) for ML, making it intuitive to discover models, solutions, and more. At launch, SageMaker JumpStart includes:

  • 15+ end-to-end solutions for common ML use cases such as fraud detection, predictive maintenance, and so on.
  • 150+ models from the TensorFlow Hub and the PyTorch Hub, for computer vision (image classification, object detection), and natural language processing (sentence classification, question answering).
  • Sample notebooks for the built-in algorithms available in Amazon SageMaker.

SageMaker JumpStart also provides notebooks, blogs, and video tutorials designed to help you learn and remove roadblocks. Content is easily accessible within Amazon SageMaker Studio, enabling you to get started with ML faster.

It only takes a single click to deploy solutions and models. All infrastructure is fully managed, so all you have to do is enjoy a nice cup of tea or coffee while deployment takes place. After a few minutes, you can start testing, thanks to notebooks and sample prediction code that are readily available in Amazon SageMaker Studio. Of course, you can easily modify them to use your own data.

SageMaker JumpStart makes it extremely easy for experienced practitioners and beginners alike to quickly deploy and evaluate models and solutions, saving days or even weeks of work. By drastically shortening the path from experimentation to production, SageMaker JumpStart accelerates ML-powered innovation, particularly for organizations and teams that are early on their ML journey, and haven’t yet accumulated a lot of skills and experience.

Now, let me show you how SageMaker JumpStart works.

Deploying a Solution with Amazon SageMaker JumpStart
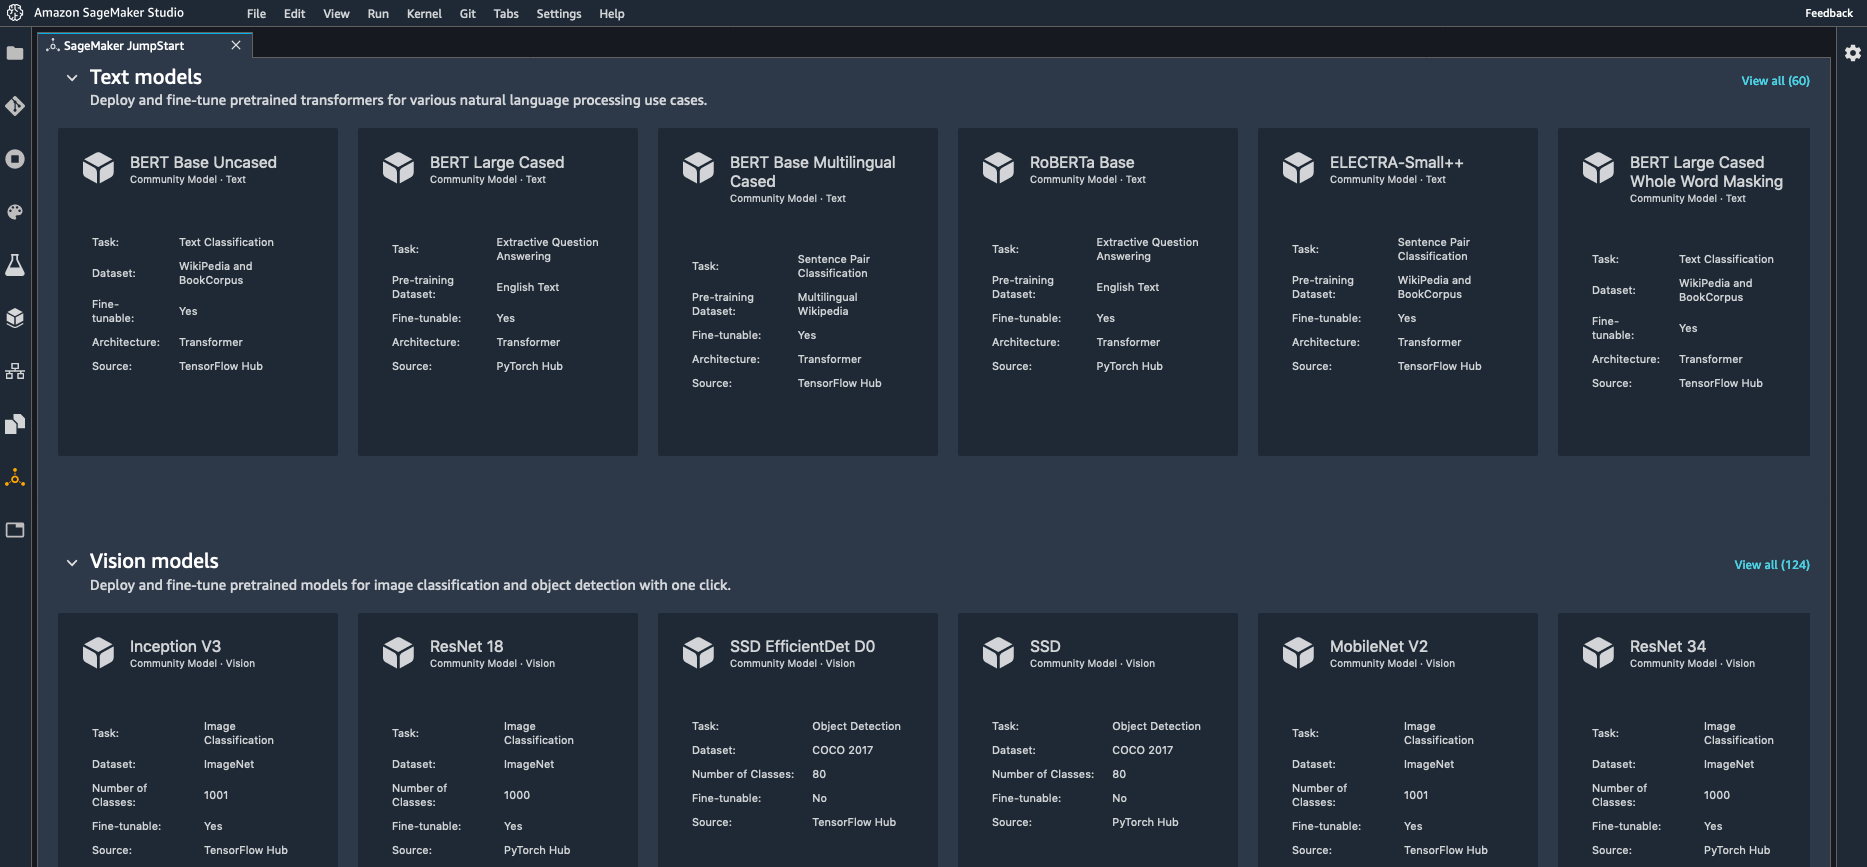
Opening SageMaker Studio, I select the “JumpStart” icon on the left. This opens a new tab showing me all available content (solutions, models, and so on).

Let’s say that I’m interested in using computer vision to detect defects in manufactured products. Could ML be the answer?

Browsing the list of available solutions, I see one for product defect detection.

Opening it, I can learn more about the type of problems that it solves, the sample dataset used in the demo, the AWS services involved, and more.

SageMaker screenshot

A single click is all it takes to deploy this solution. Under the hood, AWS CloudFormation uses a built-in template to provision all appropriate AWS resources.

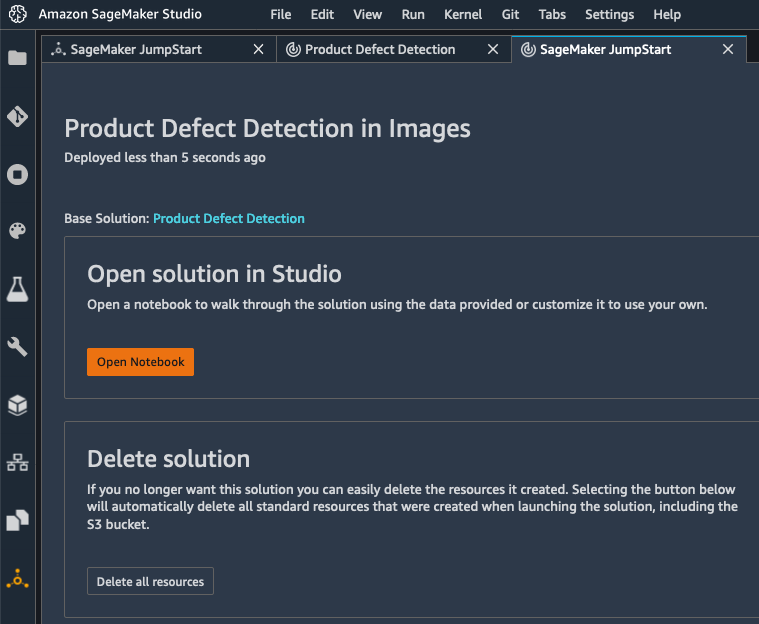
A few minutes later, the solution is deployed, and I can open its notebook.

SageMaker screenshot

The notebook opens immediately in SageMaker Studio. I run the demo, and understand how ML can help me detect product defects. This is also a nice starting point for my own project, making it easy to experiment with my own dataset (feel free to click on the image below to zoom in).

SageMaker screenshot

Once I’m done with this solution, I can delete all its resources in one click, letting AWS CloudFormation clean up without having to worry about leaving idle AWS resources behind.

SageMaker screenshot

Now, let’s look at models.

Deploying a Model with Amazon SageMaker JumpStart
SageMaker JumpStart includes a large collection of models available in the TensorFlow Hub and the PyTorch Hub. These models are pre-trained on reference datasets, and you can use them directly to handle a wide range of computer vision and natural language processing tasks. You can also fine-tune them on your own datasets for greater accuracy, a technique called transfer learning.

SageMaker screenshot
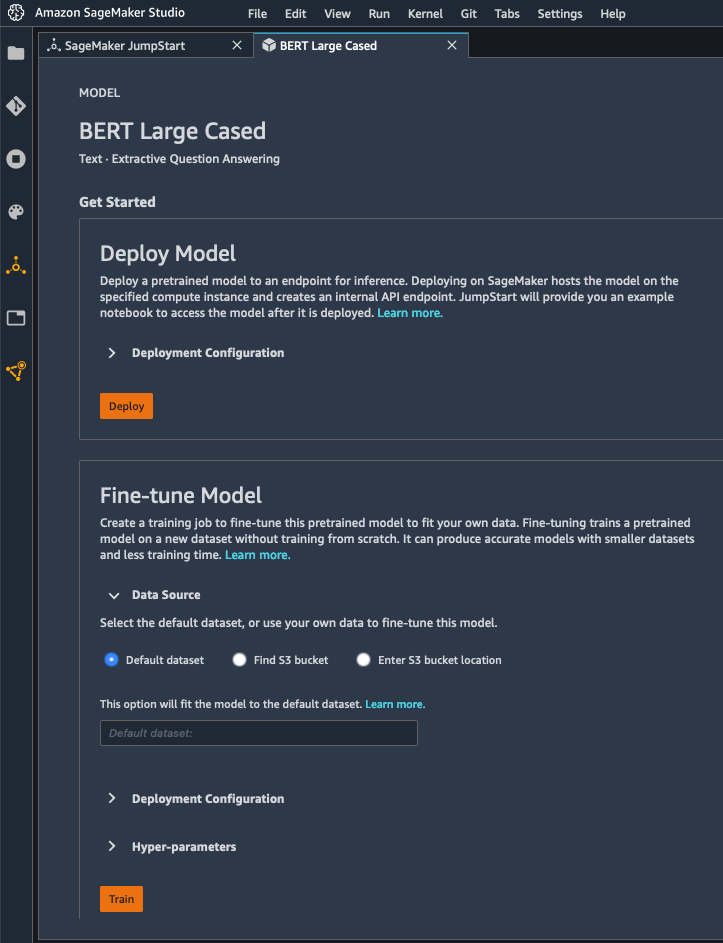
Here, I pick a version of the BERT model trained on question answering. I can either deploy it as is, or fine-tune it. For the sake of brevity, I go with the former here, and I just click on the “Deploy” button.

SageMaker screenshot

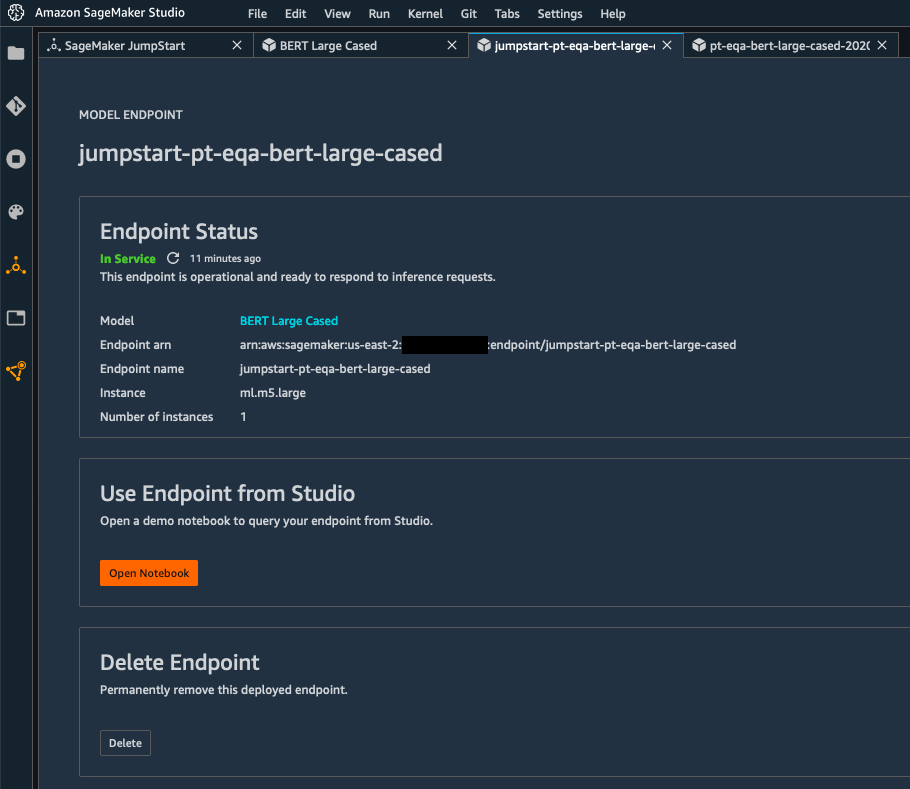
A few minutes later, the model has been deployed to a real-time endpoint powered by fully managed infrastructure.

SageMaker screenshot

Time to test it! Clicking on “Open Notebook” launches a sample notebook that I run right away to test the model, without having to change a line of code (again, feel free to click on the image below to zoom in). Here, I’m asking two questions (“What is Southern California often abbreviated as?” and “Who directed Spectre?“), passing some context containing the answer. In both cases, the BERT model gives the correct answer, respectively “socal” and “Sam Mendes“.

SageMaker screenshot

When I’m done testing, I can delete the endpoint in one click, and stop paying for it.

Getting Started
As you can see, it’s extremely easy to deploy models and solutions with SageMaker JumpStart in minutes, even if you have little or no ML skills.

You can start using this capability today in all regions where SageMaker Studio is available, at no additional cost.

Give it a try and let us know what you think.

As always, we’re looking forward to your feedback, either through your usual AWS support contacts, or on the AWS Forum for SageMaker.

- Julien

Special thanks to my colleague Jared Heywood for his precious help during early testing.

Via AWS News Blog https://ift.tt/1EusYcK

New – Amazon SageMaker Pipelines Brings DevOps Capabilities to your Machine Learning Projects

Today, I’m extremely happy to announce Amazon SageMaker Pipelines, a new capability of Amazon SageMaker that makes it easy for data scientists and engineers to build, automate, and scale end to end machine learning pipelines.

Machine learning (ML) is intrinsically experimental and unpredictable in nature. You spend days or weeks exploring and processing data in many different ways, trying to crack the geode open to reveal its precious gemstones. Then, you experiment with different algorithms and parameters, training and optimizing lots of models in search of highest accuracy. This process typically involves lots of different steps with dependencies between them, and managing it manually can become quite complex. In particular, tracking model lineage can be difficult, hampering auditability and governance. Finally, you deploy your top models, and you evaluate them against your reference test sets. Finally? Not quite, as you’ll certainly iterate again and again, either to try out new ideas, or simply to periodically retrain your models on new data.

No matter how exciting ML is, it does unfortunately involve a lot of repetitive work. Even small projects will require hundreds of steps before they get the green light for production. Over time, not only does this work detract from the fun and excitement of your projects, it also creates ample room for oversight and human error.

To alleviate manual work and improve traceability, many ML teams have adopted the DevOps philosophy and implemented tools and processes for Continuous Integration and Continuous Delivery (CI/CD). Although this is certainly a step in the right direction, writing your own tools often leads to complex projects that require more software engineering and infrastructure work than you initially anticipated. Valuable time and resources are diverted from the actual ML project, and innovation slows down. Sadly, some teams decide to revert to manual work, for model management, approval, and deployment.

Introducing Amazon SageMaker Pipelines
Simply put, Amazon SageMaker Pipelines brings in best-in-class DevOps practices to your ML projects. This new capability makes it easy for data scientists and ML developers to create automated and reliable end-to-end ML pipelines. As usual with SageMaker, all infrastructure is fully managed, and doesn’t require any work on your side.

Care.com is the world’s leading platform for finding and managing high-quality family care. Here’s what Clemens Tummeltshammer, Data Science Manager, Care.com, told us: “A strong care industry where supply matches demand is essential for economic growth from the individual family up to the nation’s GDP. We’re excited about Amazon SageMaker Feature Store and Amazon SageMaker Pipelines, as we believe they will help us scale better across our data science and development teams, by using a consistent set of curated data that we can use to build scalable end-to-end machine learning (ML) model pipelines from data preparation to deployment. With the newly announced capabilities of Amazon SageMaker, we can accelerate development and deployment of our ML models for different applications, helping our customers make better informed decisions through faster real-time recommendations.

Let me tell you more about the main components in Amazon SageMaker Pipelines: pipelines, model registry, and MLOps templates.

Pipelines – Model building pipelines are defined with a simple Python SDK. They can include any operation available in Amazon SageMaker, such as data preparation with Amazon SageMaker Processing or Amazon SageMaker Data Wrangler, model training, model deployment to a real-time endpoint, or batch transform. You can also add Amazon SageMaker Clarify to your pipelines, in order to detect bias prior to training, or once the model has been deployed. Likewise, you can add Amazon SageMaker Model Monitor to detect data and prediction quality issues.

Once launched, model building pipelines are executed as CI/CD pipelines. Every step is recorded, and detailed logging information is available for traceability and debugging purposes. Of course, you can also visualize pipelines in Amazon SageMaker Studio, and track their different executions in real time.

Model Registry – The model registry lets you track and catalog your models. In SageMaker Studio, you can easily view model history, list and compare versions, and track metadata such as model evaluation metrics. You can also define which versions may or may not be deployed in production. In fact, you can even build pipelines that automatically trigger model deployment once approval has been given. You’ll find that the model registry is very useful in tracing model lineage, improving model governance, and strengthening your compliance posture.

MLOps TemplatesSageMaker Pipelines includes a collection of built-in CI/CD templates for popular pipelines (build/train/deploy, deploy only, and so on). You can also add and publish your own templates, so that your teams can easily discover them and deploy them. Not only do templates save lots of time, they also make it easy for ML teams to collaborate from experimentation to deployment, using standard processes and without having to manage any infrastructure. Templates also let Ops teams customize steps as needed, and give them full visibility for troubleshooting.

Now, let’s do a quick demo!

Building an End-to-end Pipeline with Amazon SageMaker Pipelines
Opening SageMaker Studio, I select the “Components” tab and the “Projects” view. This displays a list of built-in project templates. I pick one to build, train, and deploy a model.

SageMaker screenshot

Then, I simply give my project a name, and create it.

A few seconds later, the project is ready. I can see that it includes two Git repositories hosted in AWS CodeCommit, one for model training, and one for model deployment.

SageMaker screenshot

The first repository provides scaffolding code to create a multi-step model building pipeline: data processing, model training, model evaluation, and conditional model registration based on accuracy. As you’ll see in the pipeline.py file, this pipeline trains a linear regression model using the XGBoost algorithm on the well-known Abalone dataset. This repository also includes a build specification file, used by AWS CodePipeline and AWS CodeBuild to execute the pipeline automatically.

Likewise, the second repository contains code and configuration files for model deployment, as well as test scripts required to pass the quality gate. This operation is also based on AWS CodePipeline and AWS CodeBuild, which run a AWS CloudFormation template to create model endpoints for staging and production.

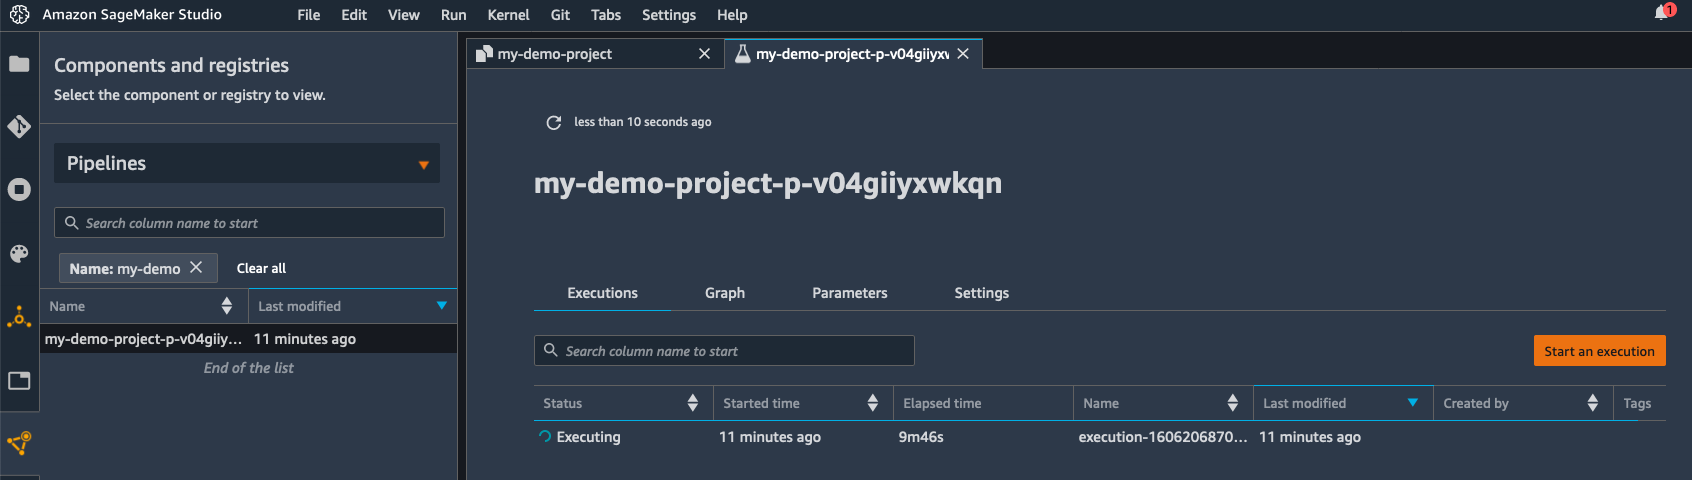
Clicking on the two blue links, I clone the repositories locally. This triggers the first execution of the pipeline.

SageMaker screenshot

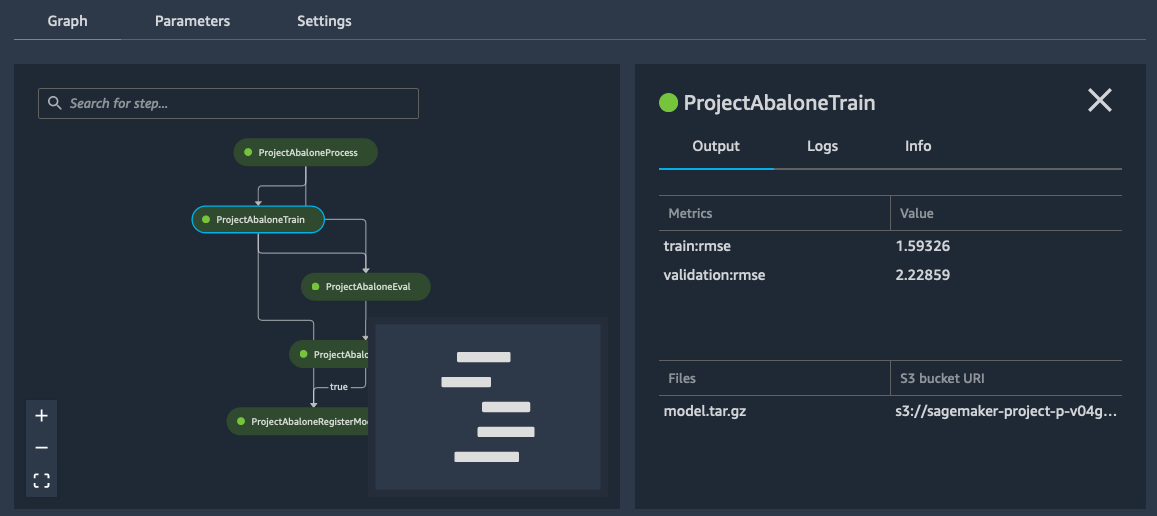
A few minutes later, the pipeline has run successfully. Switching to the “Pipelines” view, I can visualize its steps.

SageMaker screenshot

Clicking on the training step, I can see the Root Mean Square Error (RMSE) metrics for my model.

SageMaker screenshot

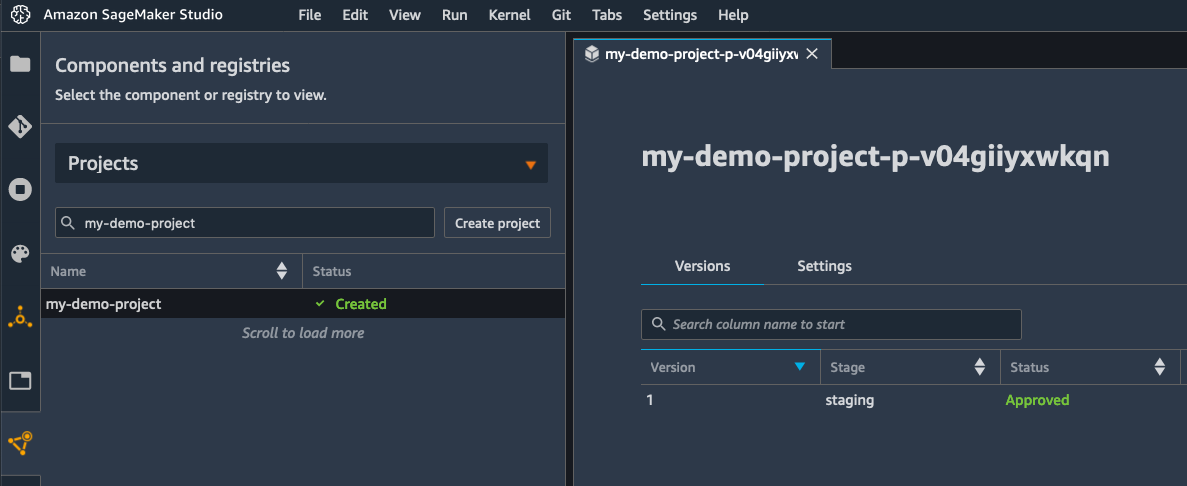
As the RMSE is lower than the threshold defined in the conditional step, my model is added to the model registry, as visible below.

SageMaker screenshot

For simplicity, the registration step sets the model status to “Approved”, which automatically triggers its deployment to a real-time endpoint in the same account. Within seconds, I see that the model is being deployed.

SageMaker screenshot

Alternatively, you could register your model with a “Pending manual approval” status. This will block deployment until the model has been reviewed and approved manually. As the model registry supports cross-account deployment, you could also easily deploy in a different account, without having to copy anything across accounts.

A few minutes later, the endpoint is up, and I could use it to test my model.

SageMaker screenshot

Once I’ve made sure that this model works as expected, I could ping the MLOps team, and ask them to deploy the model in production.

Putting my MLOps hat on, I open the AWS CodePipeline console, and I see that my deployment is indeed waiting for approval.

SageMaker screenshot

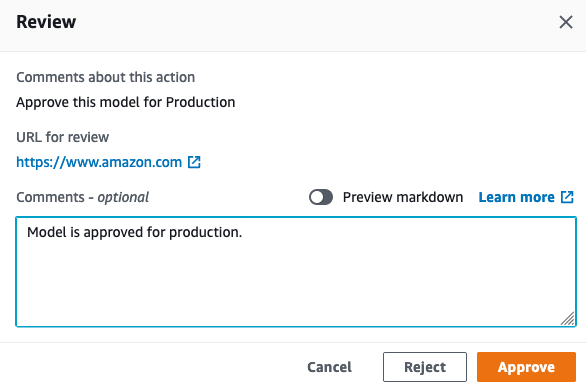
I then approve the model for deployment, which triggers the final stage of the pipeline.

SageMaker screenshot

Reverting to my Data Scientist hat, I see in SageMaker Studio that my model is being deployed. Job done!

SageMaker screenshot

Getting Started
As you can see, Amazon SageMaker Pipelines makes it really easy for Data Science and MLOps teams to collaborate using familiar tools. They can create and execute robust, automated ML pipelines that deliver high quality models in production quicker than before.

You can start using SageMaker Pipelines in all commercial regions where SageMaker is available. The MLOps capabilities are available in the regions where CodePipeline is also available.

Sample notebooks are available to get you started. Give them a try, and let us know what you think. We’re always looking forward to your feedback, either through your usual AWS support contacts, or on the AWS Forum for SageMaker.

- Julien

Special thanks to my colleague Urvashi Chowdhary for her precious assistance during early testing.

Via AWS News Blog https://ift.tt/1EusYcK

Introducing Amazon SageMaker Data Wrangler, a Visual Interface to Prepare Data for Machine Learning

Today, I’m extremely happy to announce Amazon SageMaker Data Wrangler, a new capability of Amazon SageMaker that makes it faster for data scientists and engineers to prepare data for machine learning (ML) applications by using a visual interface.

Whenever I ask a group of data scientists and ML engineers how much time they actually spend studying ML problems, I often hear a collective sigh, followed by something along the lines of, “20%, if we’re lucky.” When I ask them why, the answer is invariably the same, “data preparation consistently takes up to 80% of our time!

Indeed, preparing data for training is a crucial step of the ML process, and no one would think about botching it up. Typical tasks include:

  • Locating data: finding where raw data is stored, and getting access to it
  • Data visualization: examining statistical properties for each column in the dataset, building histograms, studying outliers
  • Data cleaning: removing duplicates, dropping or filling entries with missing values, removing outliers
  • Data enrichment and feature engineering: processing columns to build more expressive features, selecting a subset of features for training

In the early stage of a new ML project, this is a highly manual process, where intuition and experience play a large part. Using a mix of bespoke tools and open source tools such as pandas or PySpark, data scientists often experiment with different combinations of data transformations, and use them to process datasets before training models. Then, they analyze prediction results and iterate. As important as this is, looping through this process again and again can be time-consuming, tedious, and error-prone.

At some point, you will hit the right level of accuracy (or whatever other metric you’ve picked), and you’ll then want to train on the full dataset in your production environment. However, you’ll first have to reproduce and automate the exact data preparation steps that you experimented within your sandbox. Unfortunately, there’s always room for error given the interactive nature of this work, even if you carefully document it.

Last but not least, you’ll have to manage and scale your data processing infrastructure before you get to the finish line. Now that I think of it, 80% of your time may not be enough to do all of this!

Introducing Amazon SageMaker Data Wrangler
Amazon SageMaker Data Wrangler is integrated in Amazon SageMaker Studio, our fully managed integrated development environment (IDE) for ML. With just a few clicks, you can connect to data sources, explore and visualize data, apply built-in transformations as well as your own, export the resulting code to an auto-generated script, and run it on managed infrastructure. Let’s look at each step in more detail.

Obviously, data preparation starts with locating and accessing data. Out of the box, SageMaker Data Wrangler lets you easily and quickly connect to Amazon Simple Storage Service (S3), Amazon Athena, Amazon Redshift and AWS Lake Formation. You can also import data from Amazon SageMaker Feature Store. As all things AWS, access management is governed by AWS Identity and Access Management (IAM), based on the permissions attached to your SageMaker Studio instance.

Once you’ve connected to your data sources, you’ll probably want to visualize your data. Using the SageMaker Data Wrangler user interface, you can view table summaries, histograms, and scatter plots in seconds. You can also build your own custom graphs by simply copying and running code written with the popular Altair open source library.

Once you’ve got a good grasp on what your data looks like, it’s time to start preparing it. SageMaker Data Wrangler includes 300+ built-in transformations, such as finding and replacing data, splitting/renaming/dropping columns, scaling numerical values, encoding categorical values, and so on. All you have to do is select the transformation in a drop-down list, and fill in the parameters it may require. You can then preview the change, and decide whether you’d like to add it or not to the list of preparation steps for this dataset. If you’d like, you can also add your own code to implement custom transformations, using either pandas, PySpark, or PySpark SQL.

As you add transformation steps to your processing pipeline, you can view its graphical summary in SageMaker Studio. You can also add new stages to the pipeline, for example a new data source, or another group of transformation steps (say, a data cleaning group, followed by a feature engineering group). Thanks to the intuitive user interface, your data preparation pipeline will take shape in front of your eyes, and you’ll instantly be able to check that processed data looks the way that it should.

Early on, you’d certainly love to check your data preparation steps, and also get a sense of their predictive power, wouldn’t you? Good news, then! For regression and classification problem types, the “Quick model” capability lets you select a subset of your data, train a model, and determine which features are contributing most to the predicted outcome. Looking at the model, you can easily diagnose and fix data preparation issues as early as possible, and to determine if additional feature engineering is needed to improve your model performance.

Once you’re happy with your pipeline, you can export it in one click to a Python script that faithfully reproduces your manual steps. You won’t waste any time chasing discrepancies, and you can directly add this code to your ML project.

In addition, you can also export your processing code to:

Now, let’s do a quick demo, and show you how easy it is to work with SageMaker Data Wrangler .

Using Amazon SageMaker Data Wrangler
Opening SageMaker Studio, I create a new data flow in order to process the Titanic dataset, which contains information on passengers, and labels showing whether they survived the wreck or not.
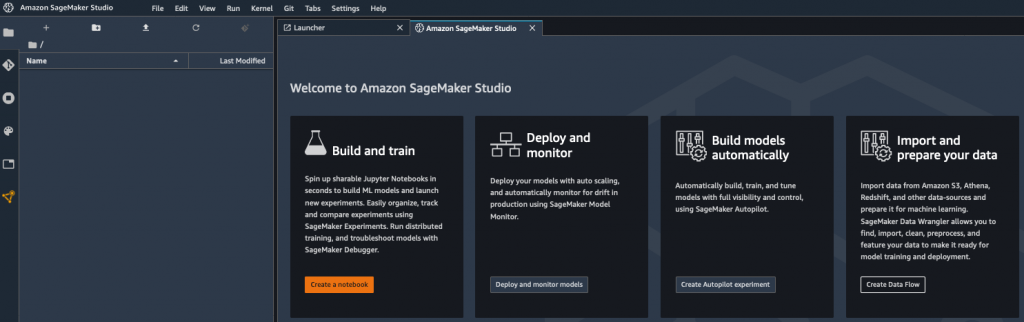
SageMaker screenshot

My dataset is stored as a CSV file in Amazon Simple Storage Service (S3), and I select the appropriate data source.
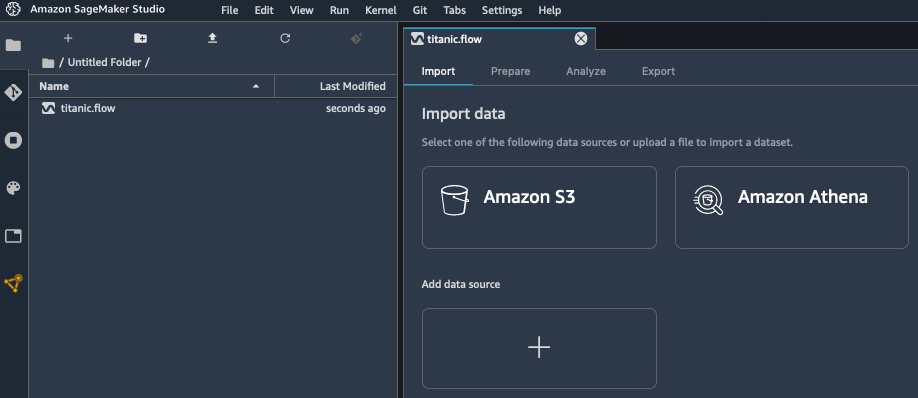
SageMaker screenshot

Using the built-in tool, I quickly navigate my S3 buckets, and I locate the CSV file containing my data. For larger datasets, SageMaker Data Wrangler also supports the Parquet format.

As I select my file, SageMaker Data Wrangler shows me the first few rows.
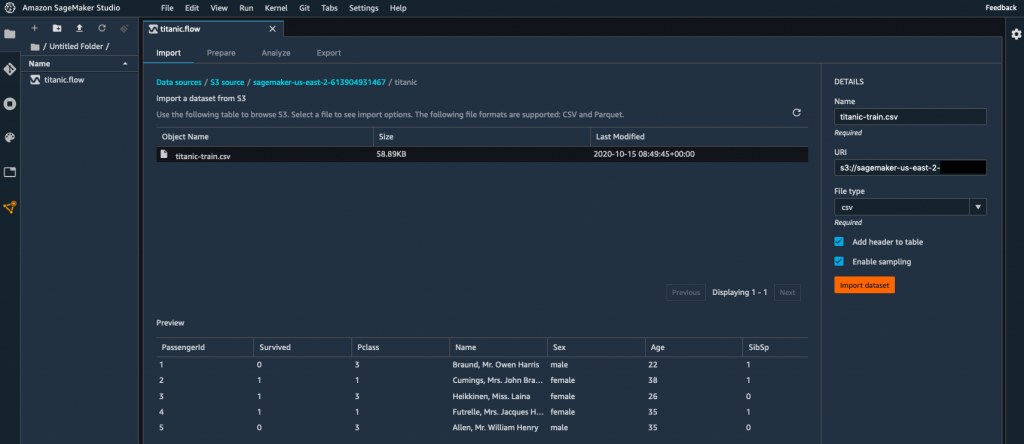
SageMaker screenshot

I import the dataset, and I’m presented with an initial view of the data flow. Right-clicking on the dataset, I select “Edit data types” to make sure that SageMaker Data Wrangler has correctly detected the type of each column in the dataset.

SageMaker screenshot

Checking each column, it looks like all types are correct.
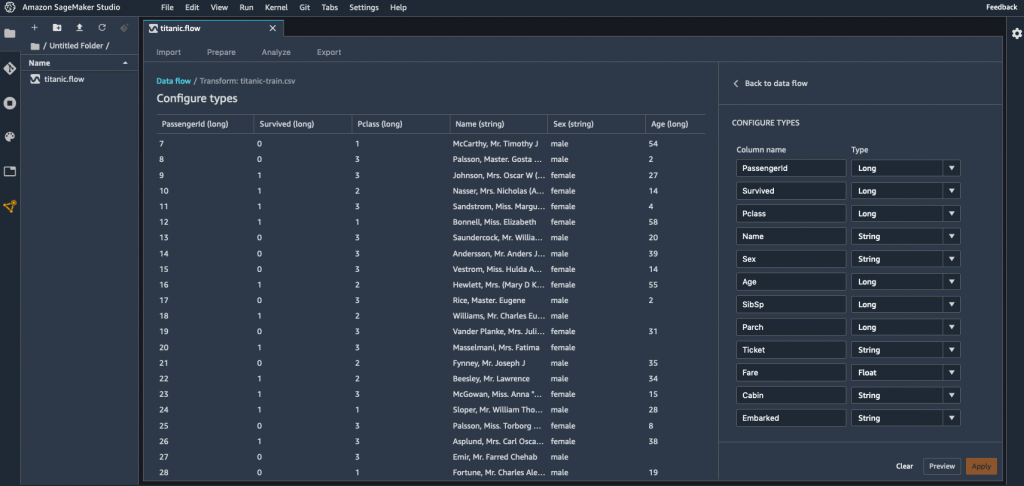
SageMaker screenshot

Moving back to the data flow view, I select “Add analysis” this time. This opens a new view where I can visualize data using histograms, scatterplots, and more. For example, I build an histogram showing me the age distribution of passengers according to their survival status, and coloring the bins using their gender. Of course, I can save it for future use.
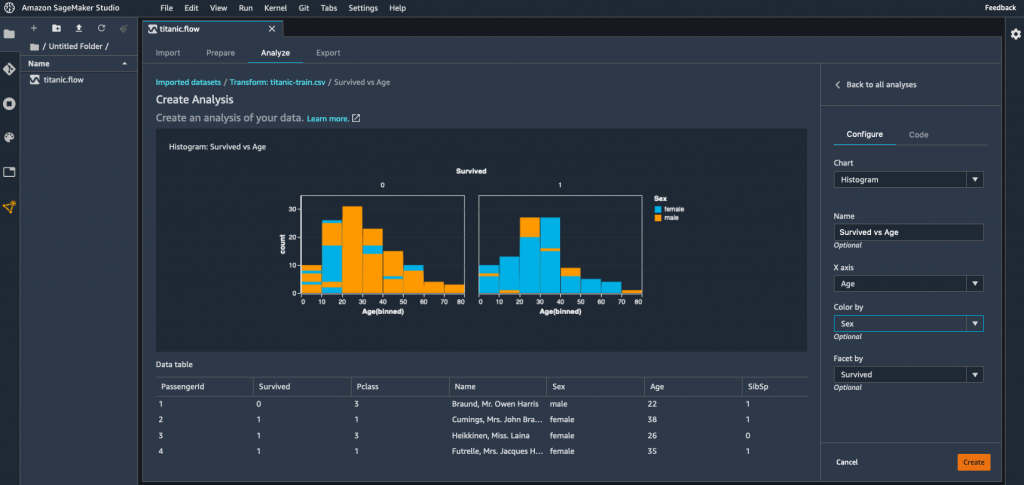
SageMaker screenshot

Moving back to the data flow view once again, I select “Add transform” in order to start processing the dataset. This opens a new view, showing me the first lines of the dataset, as well as a list of 300+ built-in transforms.
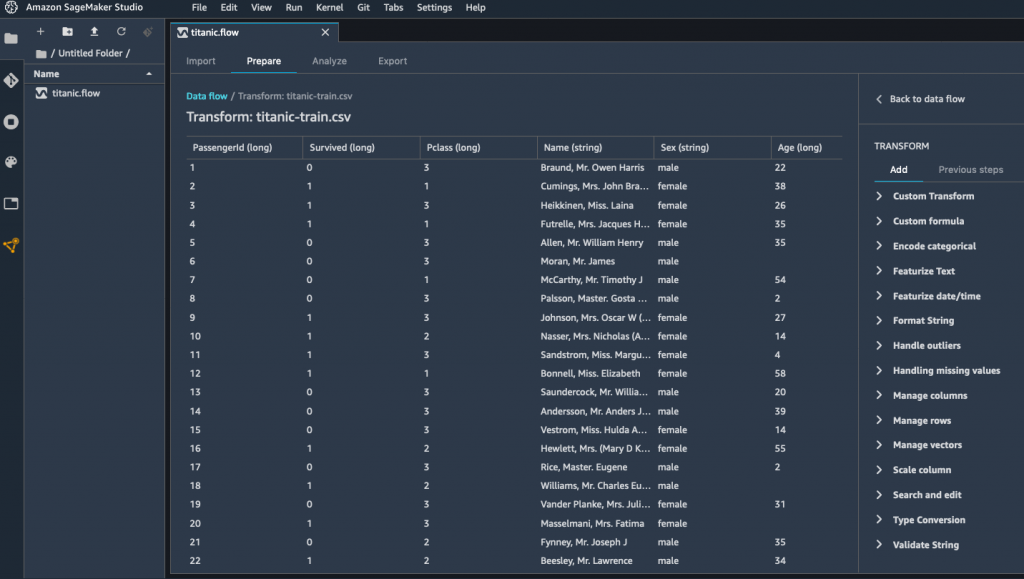
SageMaker screenshot

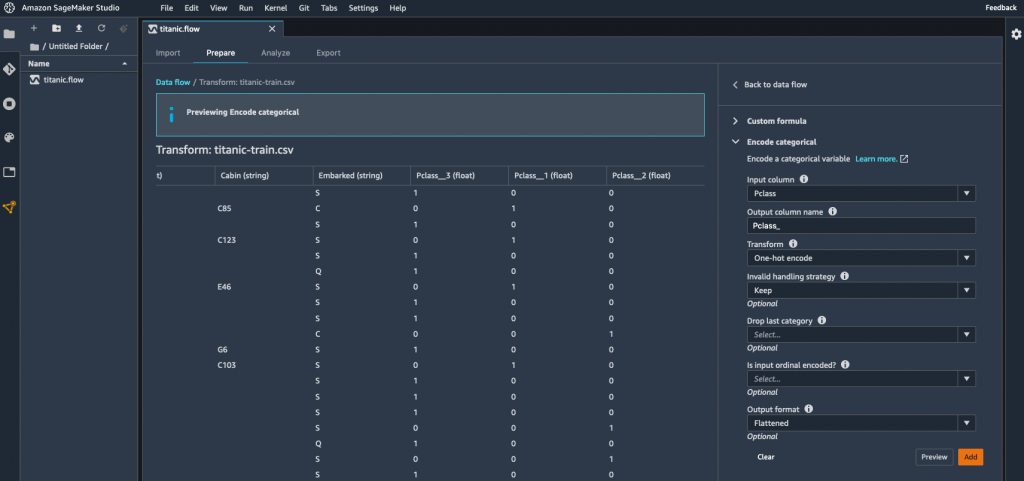
Pclass, the passenger class, is a categorical variable, and I decide to encode it using one-hot encoding. This creates 3 new columns representing different dimensions, and I can preview them. As this is exactly what I wanted, I apply this transform for good. Likewise, I apply the same transform to the Sex column.
SageMaker screenshot

Then, I drop the original Pclass column. Using the same transform, I also drop the Name column.

SageMaker screenshot

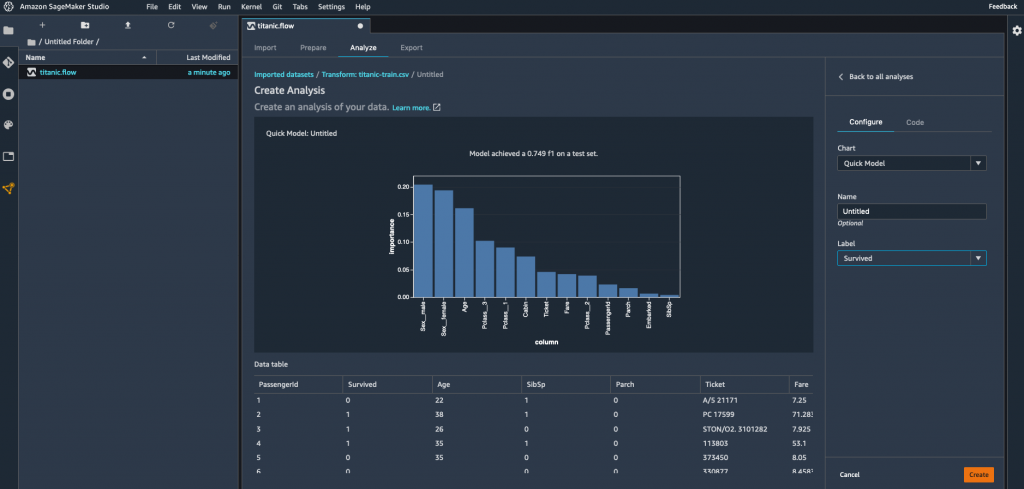
In order to get a quick idea on whether these transformations increase or decrease the accuracy of the model, I can create a analysis that trains a model on the spot. As my problem is a binary classification problem, SageMaker Data Wrangler uses a metric called the F1 score. 0.749 is a good start, and additional processing would certainly improve it. I can also see which features contribute most to the predicted outcome: sex, age, and being a third class passenger.
SageMaker screenshot

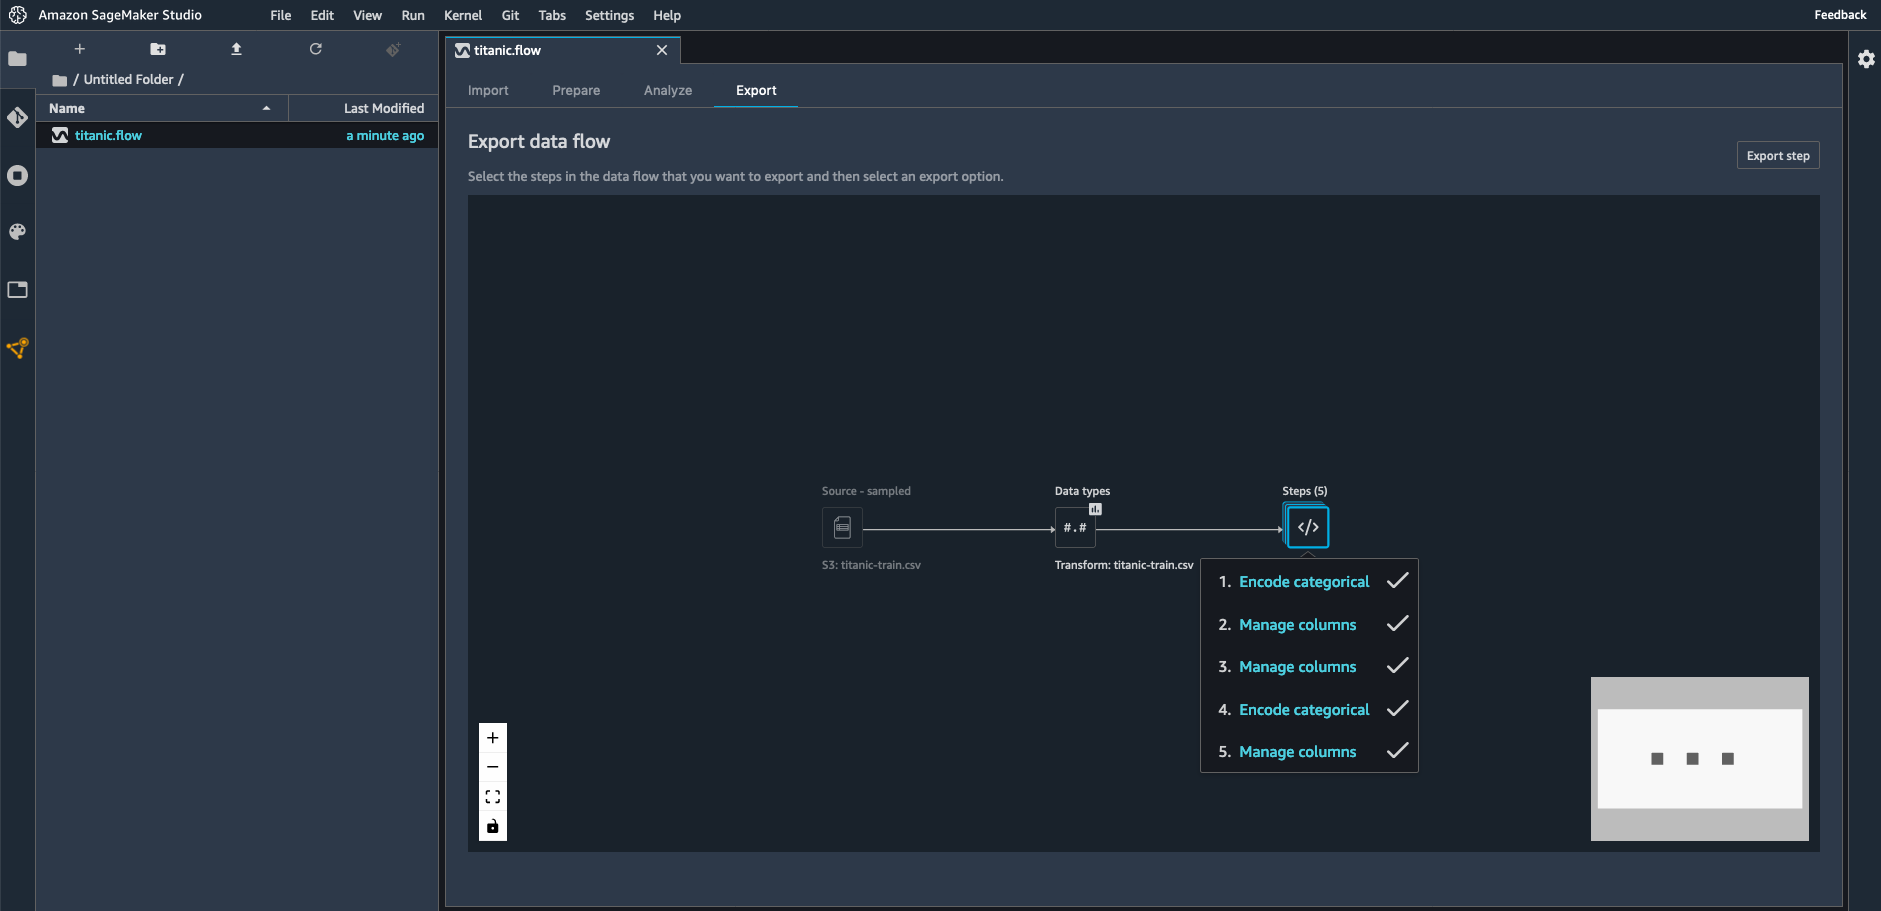
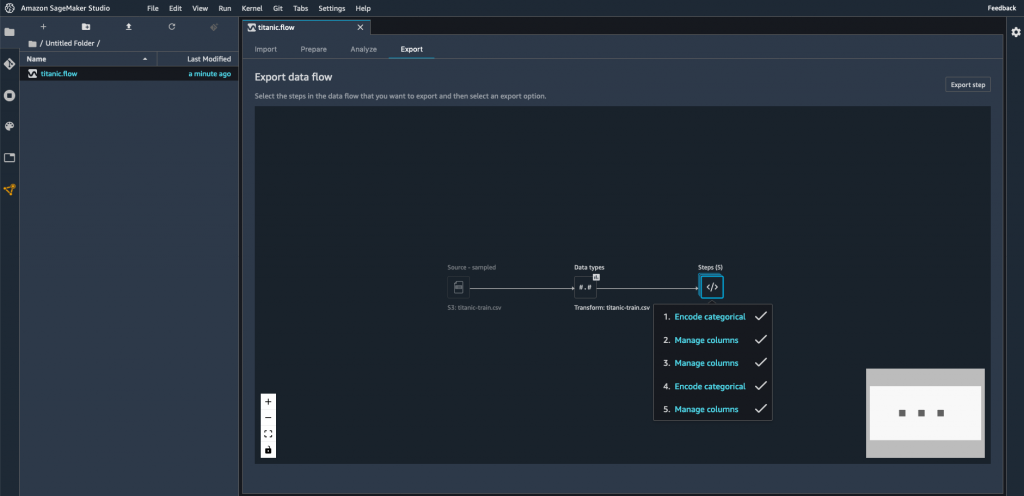
Then, moving to the “Export” view, I select all the transforms I’ve created so far, in order to add them to my ML project.
SageMaker screenshot

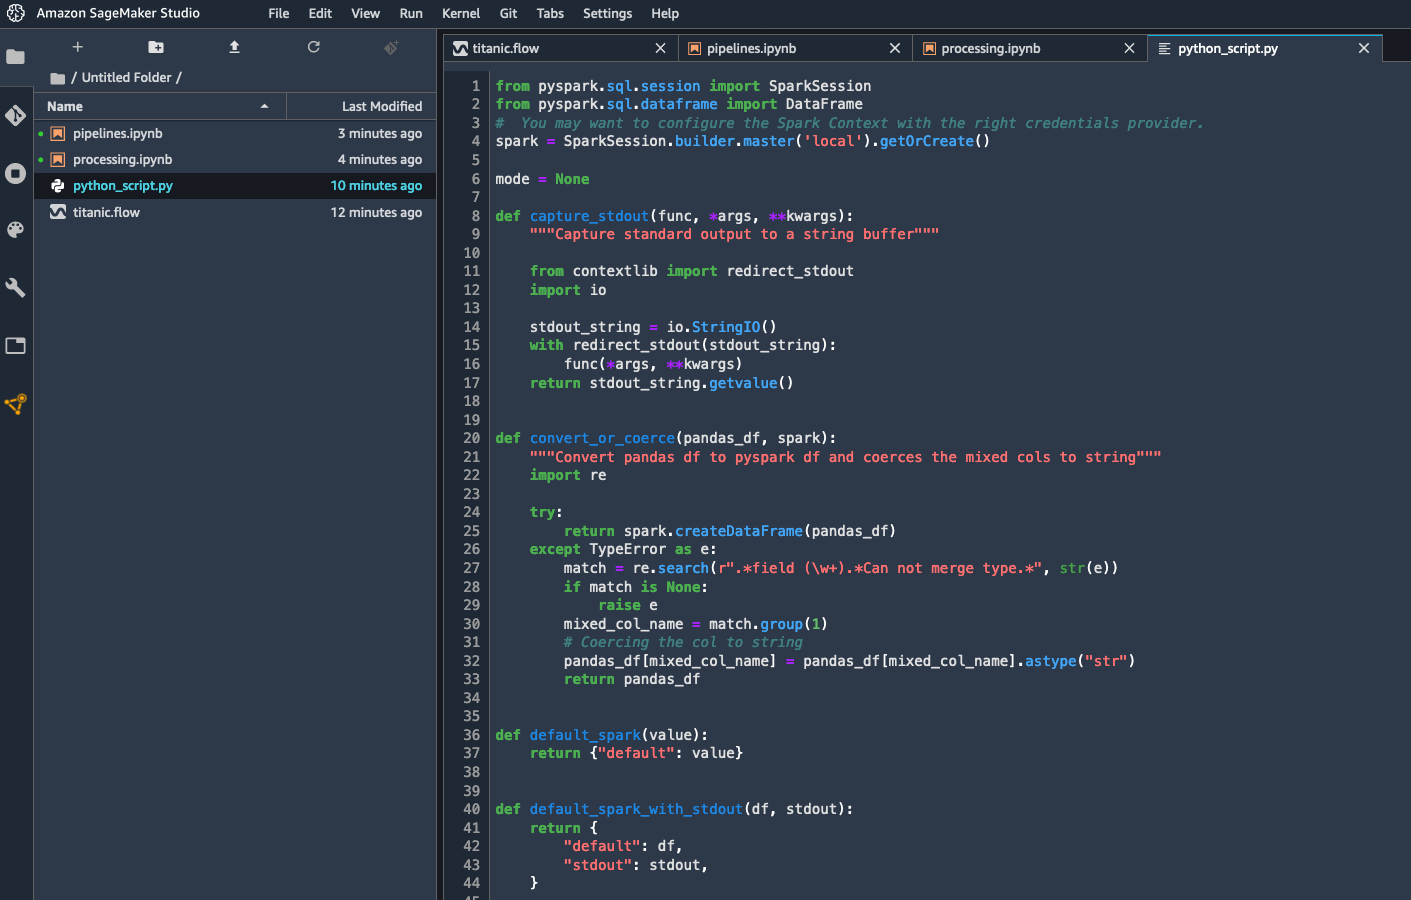
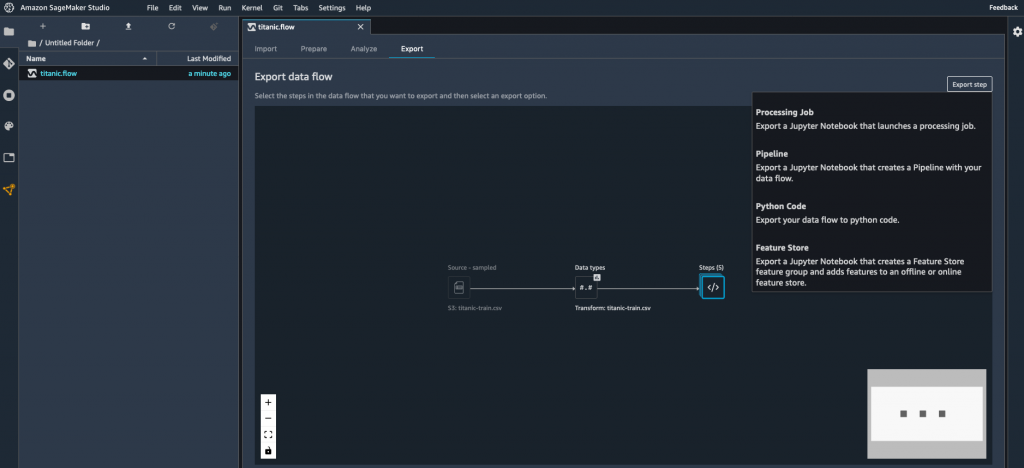
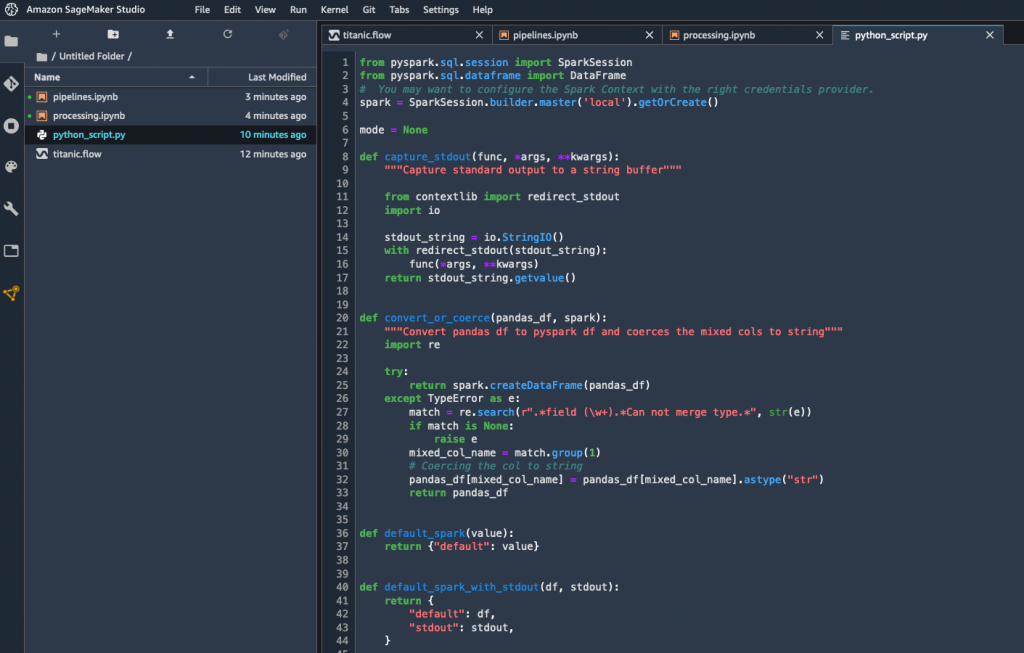
Here, I select “Python Code” to generate a Python script. Other options are available for Amazon SageMaker Processing, Amazon SageMaker Pipelines, and Amazon SageMaker Feature Store.
SageMaker screenshot

A few seconds later, the script is available. I could add it as is to my ML project, and rest assured that my data preparation steps would be consistent with the interactive transforms that I’ve created above.
SageMaker screenshot

Getting Started
As you can see, Amazon SageMaker Data Wrangler makes it really easy to work interactively on data preparation steps, before transforming them into code that can be used immediately for experimentation and production.

You can start using this capability today in all regions where SageMaker Studio is available.

Give it a try, and let us know what you think. We’re always looking forward to your feedback, either through your usual AWS support contacts, or on the AWS Forum for SageMaker.

- Julien

Special thanks to my colleague Peter Liu for his precious help during early testing.

Via AWS News Blog https://ift.tt/1EusYcK